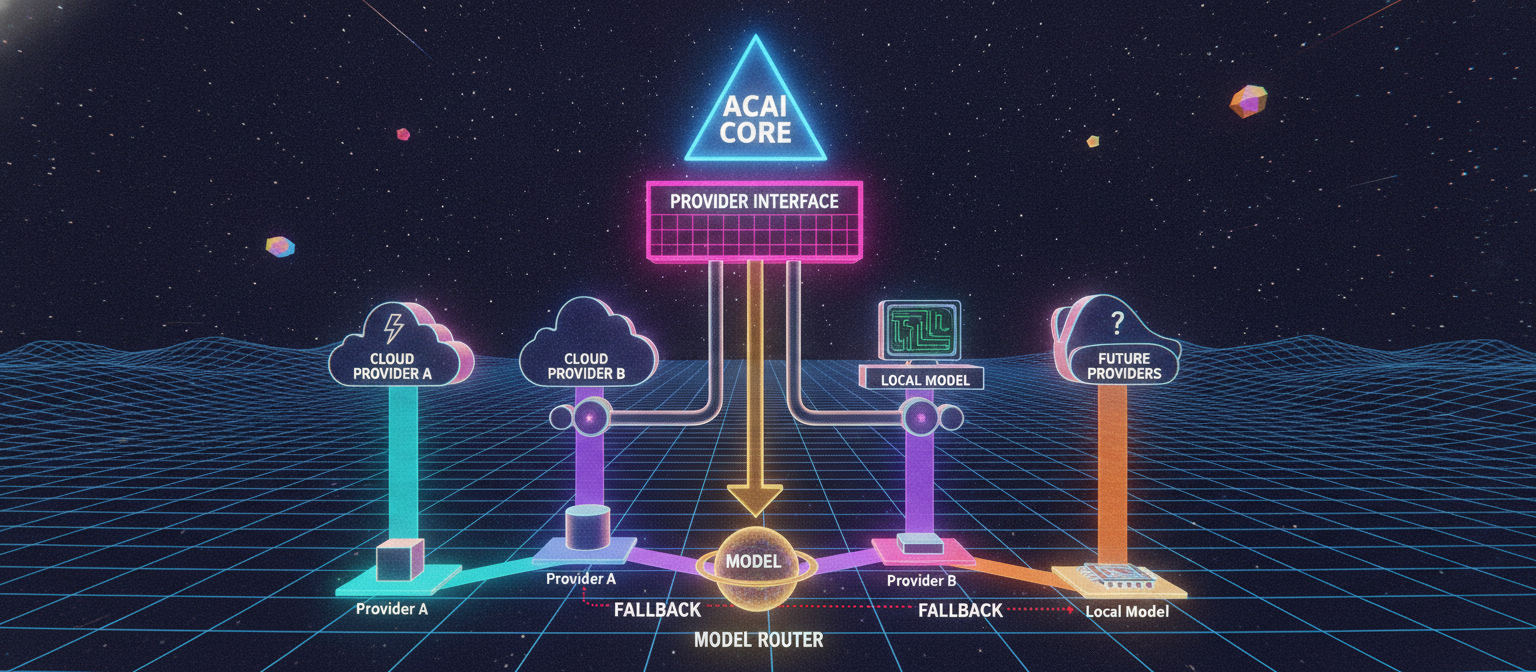
9.1 Objective
ACAI should not depend permanently on a single AI provider.
A robust architecture should separate:
ACAI Core
   ↓
Provider Interface
   ↓
Provider Adapters
   ├── Cloud Provider A
   ├── Cloud Provider B
   ├── Local Model
   └── Future Providers
The important design principle is:
The core system should know how to request an AI capability, not how every individual provider implements that capability.
9.2 Why a Provider Abstraction Is Necessary
Without an abstraction, the application can become:
Planner
   ↓
OpenAI-specific code
   ↓
OpenAI API
Then changing providers requires modifying many parts of the system.
A better design is:
Planner
   ↓
Model Router
   ↓
Provider Interface
   ↓
Selected Provider
Now the planner does not need to know whether the model is:
Cloud
Local
Open-source
Hosted
9.3 Provider Interface
Create:
app/providers/base.py
Example:
from abc import ABC, abstractmethod


class AIProvider(ABC):

    @abstractmethod
    async def generate(
        self,
        prompt: str,
        **kwargs,
    ) -> str:
        raise NotImplementedError

    @abstractmethod
    async def health_check(
        self,
    ) -> bool:
        raise NotImplementedError
Every provider must implement the same basic contract.
9.4 Provider Adapter
A provider adapter converts ACAI's internal request into the provider's API format.
Architecture:
ACAI Request
     │
     ▼
Provider Interface
     │
     ▼
Provider Adapter
     │
     ▼
External API
This prevents provider-specific implementation details from spreading throughout the application.
9.5 Mock Provider
Before connecting real services, create a mock provider.
Create:
app/providers/mock.py
from app.providers.base import AIProvider


class MockProvider(AIProvider):

    async def generate(
        self,
        prompt: str,
        **kwargs,
    ) -> str:

        return (
            "Mock response generated "
            "for: "
            f"{prompt}"
        )

    async def health_check(
        self,
    ) -> bool:

        return True
This is extremely useful for development because the application can be tested without spending API credits.
9.6 Provider Registry
Create:
app/providers/registry.py
from app.providers.base import AIProvider


class ProviderRegistry:

    def __init__(self):

        self.providers: dict[
            str,
            AIProvider
        ] = {}

    def register(
        self,
        name: str,
        provider: AIProvider,
    ) -> None:

        self.providers[name] = provider

    def get(
        self,
        name: str,
    ) -> AIProvider | None:

        return self.providers.get(name)

    def names(self) -> list[str]:

        return list(
            self.providers.keys()
        )
Example:
registry.register(
    "mock",
    MockProvider(),
)
9.7 Model Router
The model router selects a provider.
Conceptually:
                 REQUEST
                    │
                    ▼
               MODEL ROUTER
                    │
       ┌────────────┼────────────┐
       ▼            ▼            ▼
    Provider A   Provider B   Local Model
       │            │            │
       └────────────┼────────────┘
                    ▼
                 RESULT
The router can consider:
Task type
Model capability
Latency
Cost
Availability
User configuration
Provider health
9.8 Routing Policy
Create:
app/services/model_router.py
class ModelRouter:

    def __init__(
        self,
        registry,
    ):

        self.registry = registry

    async def generate(
        self,
        prompt: str,
        provider_name: str = "mock",
        **kwargs,
    ) -> str:

        provider = (
            self.registry.get(
                provider_name
            )
        )

        if provider is None:

            raise ValueError(
                f"Unknown provider: "
                f"{provider_name}"
            )

        return await provider.generate(
            prompt,
            **kwargs,
        )
This provides one internal interface:
router.generate(...)
regardless of the underlying provider.
9.9 Provider Health
Before selecting a provider, ACAI can check its health.
Conceptually:
Provider A
   │
   ▼
Healthy?
 ┌─┴─┐
YES  NO
 │    │
 ▼    ▼
Use  Fallback
However, repeatedly calling a provider's health endpoint before every request can add latency.
A production system should generally maintain cached health information rather than performing a fresh health check for every generation.
9.10 Provider Status
A provider can have:
healthy
degraded
unavailable
unknown
Example:
class ProviderStatus:

    HEALTHY = "healthy"

    DEGRADED = "degraded"

    UNAVAILABLE = "unavailable"

    UNKNOWN = "unknown"
9.11 Fallback Architecture
Suppose the preferred provider is:
Provider A
and it fails.
The router can attempt:
Provider A
   ↓
Failure
   ↓
Provider B
   ↓
Failure
   ↓
Local Model
Conceptually:
                    REQUEST
                       │
                       ▼
                  Provider A
                       │
                 ┌─────┴─────┐
                 ▼           ▼
              SUCCESS      FAILURE
                 │           │
                 ▼           ▼
               RESULT    Provider B
                              │
                        ┌─────┴─────┐
                        ▼           ▼
                     SUCCESS      FAILURE
                        │           │
                        ▼           ▼
                      RESULT    Local Model
9.12 Fallback Must Be Controlled
Fallback should not mean:
Try providers forever.
It should have:
Maximum attempts
Timeout
Allowed providers
Error classification
Logging
Termination condition
Example:
MAX_PROVIDER_ATTEMPTS = 3
9.13 Provider Error Classification
Not every failure should trigger fallback.
Examples:
Authentication failure
Invalid request
Rate limit
Timeout
Temporary server error
Network error
A policy can classify them as:
Transient
Permanent
For example:
Timeout
→ potentially transient
→ fallback may be appropriate

Invalid request
→ permanent
→ fallback may not solve the underlying problem
9.14 Provider Result Object
Instead of returning only a string, create a structured result.
from dataclasses import dataclass


@dataclass
class ProviderResult:

    text: str

    provider: str

    model: str | None = None

    latency_ms: float | None = None

    success: bool = True

    error: str | None = None
Now ACAI can record how the result was generated.
9.15 Measuring Latency
Use a timer:
import time


start = time.perf_counter()

result = await provider.generate(
    prompt
)

elapsed = (
    time.perf_counter()
    - start
)

latency_ms = elapsed * 1000
This provides measurable provider performance.
9.16 Cost Awareness
Different providers can have different pricing.
The router can eventually maintain metadata:
provider_info = {

    "provider_a": {
        "cost_class": "high",
        "latency_class": "low",
    },

    "provider_b": {
        "cost_class": "low",
        "latency_class": "medium",
    },

    "local": {
        "cost_class": "compute_only",
        "latency_class": "variable",
    },
}
The actual prices should come from current provider pricing documentation rather than being hardcoded as permanent assumptions.
9.17 Task-Aware Routing
Not every task requires the same model.
For example:
Simple classification
→ Smaller model

Complex reasoning
→ More capable model

Local/private processing
→ Local model

High-volume inexpensive task
→ Lower-cost provider
The architecture becomes:
                 TASK
                   │
                   ▼
             TASK CLASSIFIER
                   │
          ┌────────┼────────┐
          ▼        ▼        ▼
        Simple   Complex   Private
          │        │        │
          ▼        ▼        ▼
       Model A   Model B   Local
9.18 Router Policy
A basic policy might be:
ROUTING_POLICY = {

    "simple": [
        "provider_a",
        "provider_b",
    ],

    "complex": [
        "provider_b",
        "provider_a",
    ],

    "private": [
        "local",
    ],
}
The important point is that the routing policy is configuration rather than hardcoded throughout the application.
9.19 Fallback Router
A simple implementation:
class FallbackRouter:

    def __init__(
        self,
        registry,
    ):

        self.registry = registry

    async def generate(
        self,
        prompt: str,
        providers: list[str],
        **kwargs,
    ):

        errors = []

        for name in providers:

            provider = (
                self.registry.get(name)
            )

            if provider is None:

                errors.append(
                    f"{name}: not registered"
                )

                continue

            try:

                result = (
                    await provider.generate(
                        prompt,
                        **kwargs,
                    )
                )

                return result

            except Exception as exc:

                errors.append(
                    f"{name}: {exc}"
                )

        raise RuntimeError(
            "All providers failed: "
            + "; ".join(errors)
        )
This is a prototype and should later be enhanced with explicit timeout and error classification.
9.20 Timeout-Aware Provider Calls
Use:
import asyncio


result = await asyncio.wait_for(
    provider.generate(
        prompt,
        **kwargs,
    ),
    timeout=60,
)
Then a provider that exceeds the limit does not block the complete workflow indefinitely.
9.21 Complete Provider Pipeline
The resulting architecture is:
                         USER REQUEST
                              │
                              ▼
                           PLANNER
                              │
                              ▼
                         TASK TYPE
                              │
                              ▼
                        MODEL ROUTER
                              │
                    ┌─────────┼─────────┐
                    ▼         ▼         ▼
                Provider A Provider B Local
                    │         │         │
                    └─────────┼─────────┘
                              ▼
                           RESULT
                              │
                              ▼
                         VERIFICATION
                              │
                         ┌────┴────┐
                         ▼         ▼
                       PASS      REVISE
                         │         │
                         ▼         ▼
                       FINAL     RETRY
9.22 Local Model Integration
A local provider should follow exactly the same interface.
class LocalProvider(AIProvider):

    async def generate(
        self,
        prompt: str,
        **kwargs,
    ) -> str:

        # Connect to the configured
        # local model server here.

        return "Local model response"

    async def health_check(
        self,
    ) -> bool:

        return True
The important architectural property is:
ACAI Core
   ↓
AIProvider
   ↓
LocalProvider
rather than:
ACAI Core
   ↓
Local-model-specific implementation
everywhere.
9.23 Environment-Based Provider Selection
Configuration:
ACAI_DEFAULT_PROVIDER=mock
ACAI_FALLBACK_PROVIDERS=mock
For development:
mock
For a real deployment:
provider_a
provider_b
local
can be configured according to the actual providers and credentials available.
9.24 API Key Management
Provider credentials must be loaded from environment variables or a secure secret manager.
Example:
PROVIDER_A_API_KEY=...
PROVIDER_B_API_KEY=...
Do not put keys directly into:
Python source
Git repository
Frontend JavaScript
Public documentation
Screenshots
The backend should be the component that communicates with privileged provider APIs.
9.25 Frontend Security
A browser application should never receive a private provider API key simply because the frontend needs to generate an AI response.
Instead:
Browser
   ↓
ACAI Backend
   ↓
Provider API
not:
Browser
   ↓
Private API Key
   ↓
Provider API
9.26 Provider Usage Logging
Each generation should ideally record:
request_id
provider
model
task_type
latency
success
error
Example:
logger.info(
    "AI generation completed",
    extra={
        "request_id": request_id,
        "provider": provider_name,
        "model": model_name,
        "latency_ms": latency_ms,
    },
)
This enables later analysis.
9.27 Provider Metrics
Useful metrics include:
Requests
Success rate
Failure rate
Average latency
P95 latency
Timeout count
Rate-limit count
Fallback count
Example:
Provider A
Success: 98%
Fallback: 2%
Average latency: measured from production
These numbers must come from actual measurements, not assumptions.
9.28 Fallback Metrics
One particularly important metric is:
fallback_rate
If:
1000 requests
50 required fallback
then:
fallback_rate = 5%
A high fallback rate may indicate:
Provider instability
Bad timeout configuration
Rate limiting
Incorrect routing
Credential problems
Network issues
9.29 Testing the Mock Provider
Create:
tests/test_provider.py
import pytest

from app.providers.mock import (
    MockProvider,
)


@pytest.mark.asyncio
async def test_mock_provider():

    provider = MockProvider()

    result = await provider.generate(
        "Hello"
    )

    assert "Hello" in result
Health test:
@pytest.mark.asyncio
async def test_mock_health():

    provider = MockProvider()

    assert (
        await provider.health_check()
        is True
    )
9.30 Testing Fallback
Create a failing provider:
class FailingProvider:

    async def generate(
        self,
        prompt,
        **kwargs,
    ):

        raise RuntimeError(
            "Provider unavailable"
        )
Then configure:
Failing Provider
      ↓
Mock Provider
Expected:
First provider
→ FAIL

Fallback provider
→ SUCCESS
9.31 Fallback Test
Conceptually:
@pytest.mark.asyncio
async def test_fallback():

    registry = ProviderRegistry()

    registry.register(
        "failing",
        FailingProvider(),
    )

    registry.register(
        "mock",
        MockProvider(),
    )

    router = FallbackRouter(
        registry
    )

    result = await router.generate(
        prompt="hello",
        providers=[
            "failing",
            "mock",
        ],
    )

    assert "hello" in result
9.32 Testing All Providers
The system should eventually have tests for:
Provider registration
Unknown provider
Successful generation
Timeout
Transient failure
Permanent failure
Fallback
All providers failing
Health state
Logging
Metrics
9.33 Provider Independence
The most important architectural outcome of Chapter 9 is:
             ACAI CORE
                 │
          AIProvider Interface
                 │
       ┌─────────┼─────────┐
       ▼         ▼         ▼
   Provider A Provider B Local
This means adding another provider should require primarily:
New Adapter
+
Configuration
+
Tests
rather than rewriting the entire application.
9.34 Complete ACAI Architecture
After Chapter 9:
                                  USER
                                    │
                                    ▼
                               API GATEWAY
                                    │
                        ┌───────────┴───────────┐
                        ▼                       ▼
                   RATE LIMITER             REQUEST ID
                        │                       │
                        └───────────┬───────────┘
                                    ▼
                              ORCHESTRATOR
                                    │
                 ┌──────────────────┼──────────────────┐
                 ▼                  ▼                  ▼
              PLANNER            MEMORY            RETRIEVAL
                 │                  │                  │
                 │                  ▼                  │
                 │              DATABASE               │
                 │                                     │
                 └──────────────────┬──────────────────┘
                                    ▼
                              WORKFLOW ENGINE
                                    │
                                    ▼
                               MODEL ROUTER
                                    │
                     ┌──────────────┼──────────────┐
                     ▼              ▼              ▼
                 Provider A      Provider B       Local
                     │              │              │
                     └──────────────┼──────────────┘
                                    ▼
                               GENERATION
                                    │
                                    ▼
                               VERIFICATION
                                    │
                              ┌─────┴─────┐
                              ▼           ▼
                            PASS        REVISE
                              │           │
                              ▼           ▼
                            RESULT      RETRY
                              │
                  ┌───────────┼───────────┐
                  ▼           ▼           ▼
                CACHE        LOGS       METRICS
9.35 What ACAI Can Now Demonstrate
The architecture can now demonstrate a realistic modular AI pipeline:
User
 ↓
Request Validation
 ↓
Planning
 ↓
Workflow Creation
 ↓
Memory / Retrieval
 ↓
Task Routing
 ↓
Provider Selection
 ↓
AI Generation
 ↓
Fallback if appropriate
 ↓
Verification
 ↓
Result
 ↓
Persistent Logging
This is a meaningful engineering architecture.
It is not, by itself, proof of AGI or human-level intelligence.
9.36 Chapter 9 Success Criteria
Chapter 9 is complete when:
[✓] Provider interface exists
[✓] Mock provider works
[✓] Provider registry works
[✓] Model router exists
[✓] Fallback router exists
[✓] Timeout handling exists
[✓] Provider health is defined
[✓] Provider errors are classified
[✓] API keys are externalized
[✓] Provider usage is logged
[✓] Provider metrics are defined
[✓] Fallback is tested
[✓] Local-provider architecture is supported
9.37 Next Chapter
The system now has:
Planning
Retrieval
Memory
Routing
Verification
Workflow
Persistence
Infrastructure
Multi-provider execution
Fallback
The next major problem is evaluation.
An AI system cannot be considered reliable merely because:
API returns 200
or:
Model generated text
We need to measure whether the system actually performs its intended tasks correctly.
Therefore the next chapter is:
Chapter 10 — Evaluation, Benchmarking, Quality Measurement, and Research Validation
It will cover:
Evaluation datasets
Test cases
Task success metrics
Accuracy
Factuality
Latency
Reliability
Regression testing
Human evaluation
Automated evaluation
Benchmark design
A/B testing
Failure analysis
Reproducibility
Research reporting
The architecture will move from:
"It works."
to:
"Here is what it does,
how well it does it,
where it fails,
and how we measured it."
End of Chapter 9


Comments
Post a Comment