13.1 Introduction
A sophisticated AI architecture cannot be considered successful merely because the software runs.
The central research question is:
Does the additional ACAI architecture measurably improve performance compared with a simpler baseline?
Chapter 13 defines a practical framework for answering that question.
The testing system should evaluate not only answer accuracy, but also retrieval quality, reasoning performance, latency, cost, reliability, and failure behavior.
The most important principle is:
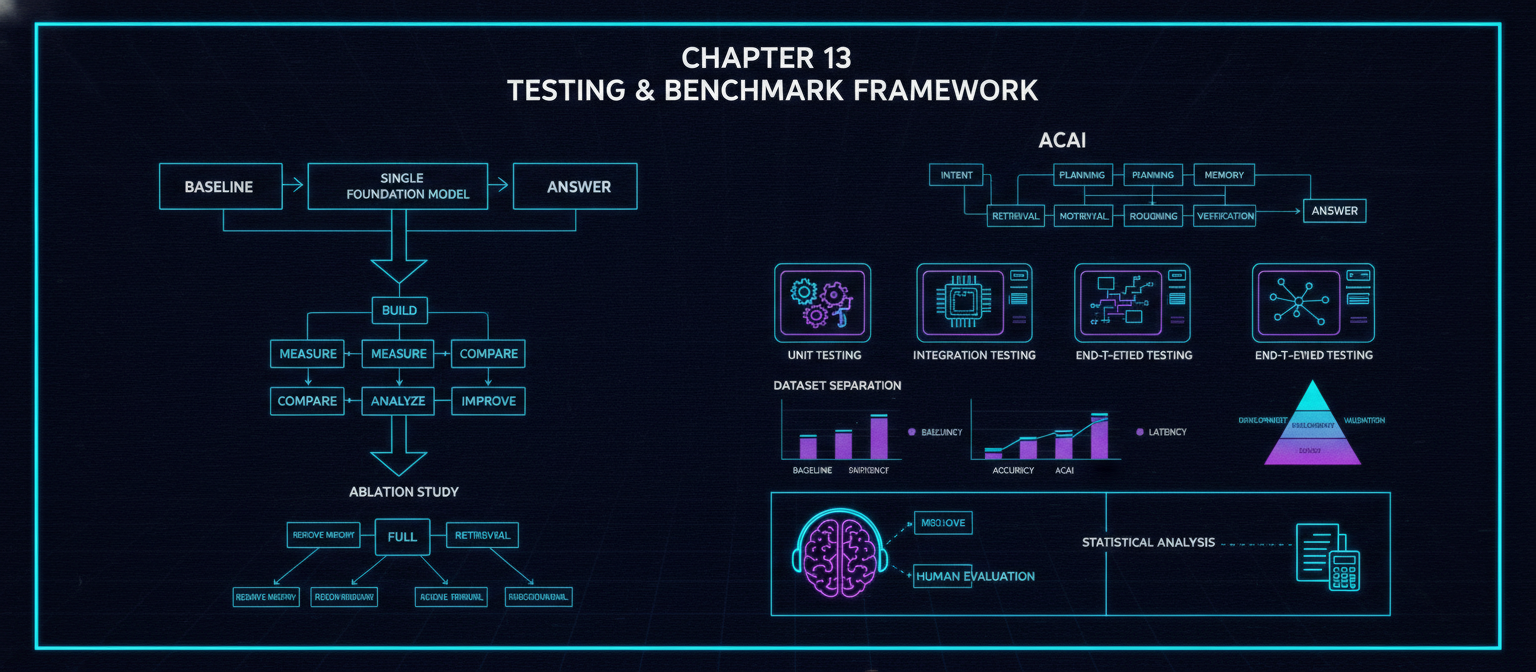
13.2 Baseline vs ACAI
The first requirement is a baseline.
Baseline
ACAI
The two systems should be evaluated on the same task set.
Otherwise, the comparison may not be meaningful.
13.3 Research Hypothesis
A testable hypothesis could be:
ACAI will achieve higher task-completion and answer-quality scores than the baseline on selected complex tasks, while introducing additional latency and computational overhead.
This is a hypothesis.
It should not be presented as a result until experiments demonstrate it.
13.4 Benchmark Dataset
The benchmark should represent the intended use cases.
Example categories:
A balanced benchmark prevents the system from appearing strong simply because it was tested on its easiest capability.
13.5 Dataset Structure
Each test case can contain:
Not every task requires a single reference answer.
For open-ended tasks, evaluation can instead use a rubric.
13.6 Dataset Separation
The evaluation dataset should be separated into different subsets.
The final test set should not repeatedly be used during development.
Otherwise, developers may unintentionally optimize the system specifically for those examples.
13.7 Unit Testing
Every individual component should have tests.
Examples:
Unit tests make component-level failures easier to identify.
13.8 Integration Testing
Integration testing verifies whether multiple components work together.
Example:
The objective is to detect failures that do not appear when components are tested independently.
13.9 End-to-End Testing
End-to-end testing evaluates the complete application.
A complete test might verify:
13.10 Retrieval Benchmark
The retrieval subsystem requires independent testing.
Useful metrics include:
Precision
Of the retrieved documents, how many are relevant?
Recall
Of the relevant available documents, how many were retrieved?
Ranking Quality
Are the most useful documents appearing near the top?
Example:
This can be evaluated systematically using a labeled dataset.
13.11 Context Quality
Retrieval alone does not guarantee good context.
The benchmark should evaluate:
Questions:
-
Was important information preserved?
-
Was irrelevant information removed?
-
Were sources correctly associated?
-
Was the context too large?
-
Were conflicting sources identified?
13.12 Planning Benchmark
The planner can be evaluated using task decomposition.
Example:
Metrics can include:
-
Task coverage
-
Dependency correctness
-
Redundant-task rate
-
Invalid-task rate
-
Completion rate
13.13 Model Routing Benchmark
The router should be evaluated separately.
Example:
Then compare:
Useful metrics include:
-
Routing accuracy
-
Task success
-
Average latency
-
Cost
-
Fallback rate
13.14 Memory Benchmark
Memory should be tested for both retrieval and correctness.
Example:
The test should determine:
-
Was the correct memory retrieved?
-
Was irrelevant memory ignored?
-
Was outdated information handled correctly?
-
Did memory improve task completion?
13.15 Reasoning Evaluation
Reasoning quality should be measured through the final task outcome rather than assuming that longer hidden reasoning means better reasoning.
Possible benchmark categories:
The evaluation should focus on correctness and task completion.
13.16 Verification Benchmark
Create examples containing known errors.
Example:
Possible metrics:
Detection Rate
How often are known errors detected?
False Positive Rate
How often does the verifier incorrectly reject a correct answer?
Correction Rate
How often is a detected error actually corrected?
13.17 Confidence Calibration
A confidence score is useful only if it corresponds reasonably well with actual correctness.
Example:
would represent good calibration.
But:
would indicate overconfidence.
Therefore, confidence should be evaluated statistically rather than simply displayed to users.
13.18 Latency Benchmark
Measure the time required for each stage.
Example:
This allows engineers to identify the largest bottleneck.
13.19 Cost Benchmark
For cloud-based systems, cost should be measured per request or per completed task.
Example:
A more complex architecture is not automatically better if its performance improvement is too small relative to its resource cost.
13.20 Load Testing
The system should be tested under increasing concurrency.
Measure:
-
Response latency
-
Error rate
-
Throughput
-
CPU utilization
-
GPU utilization
-
Memory utilization
-
Queue depth
The actual maximum capacity should come from experiments.
13.21 Stress Testing
Stress testing intentionally pushes the system beyond expected normal load.
Example:
The objective is to understand how the system fails and whether it recovers safely.
13.22 Failure Testing
The system should deliberately simulate failures.
Examples:
Expected behavior:
13.23 Regression Testing
Every major update should run the previous benchmark suite.
Example:
If a new feature improves programming but significantly damages document retrieval, the regression test should reveal it.
13.24 Ablation Study
Ablation testing is one of the most important experiments for ACAI.
Start with:
Then remove components individually.
Compare the results.
This determines which components actually contribute to performance.
13.25 Example Ablation Table
| Configuration | Accuracy | Latency | Cost |
|---|
| Baseline | Measure | Measure | Measure |
| + Planning | Measure | Measure | Measure |
| + Retrieval | Measure | Measure | Measure |
| + Memory | Measure | Measure | Measure |
| + Routing | Measure | Measure | Measure |
| + Verification | Measure | Measure | Measure |
| Full ACAI | Measure | Measure | Measure |
The values must come from real experiments.
They should never be fabricated.
13.26 Human Evaluation
Some tasks cannot be evaluated completely by automated metrics.
Human reviewers can score responses using a standardized rubric.
Example:
| Criterion | 1 | 3 | 5 |
|---|
| Correctness | Poor | Moderate | Excellent |
| Relevance | Poor | Moderate | Excellent |
| Clarity | Poor | Moderate | Excellent |
| Completeness | Poor | Moderate | Excellent |
| Evidence | Poor | Moderate | Excellent |
Multiple evaluators can independently score the same samples.
13.27 Blind Evaluation
When possible, reviewers should not know whether a response came from:
or
This reduces evaluation bias.
A practical setup:
The system identity can be revealed only after scoring.
13.28 Statistical Analysis
If the dataset is sufficiently large, researchers can apply statistical analysis to determine whether observed differences are likely meaningful.
Report:
-
Sample size
-
Mean
-
Median
-
Variance
-
Confidence intervals where appropriate
-
Statistical tests where appropriate
-
Effect size
A small numerical improvement should not automatically be described as a meaningful improvement.
13.29 Reproducibility
A serious research evaluation should record:
This allows another researcher to reproduce the experiment.
13.30 Benchmark Report
A final benchmark report should contain:
13.31 What Would Constitute Strong Evidence?
A strong result would look like:
Then the improvement should be:
-
Repeated across multiple task categories
-
Statistically or practically meaningful
-
Reproducible
-
Not limited to one hand-picked example
-
Reported together with failure cases
13.32 Negative Results
Negative results are scientifically valuable.
For example:
That result should still be published honestly.
It may indicate that the architecture is useful only for certain workloads.
13.33 Practical Testing Pipeline
13.34 Final Benchmark Architecture
13.35 Chapter Summary
A functioning prototype alone cannot demonstrate that ACAI is better than a conventional language-model system.
The testing framework therefore establishes a controlled methodology based on:
-
Baseline comparison
-
Component-level testing
-
Integration testing
-
End-to-end testing
-
Retrieval evaluation
-
Planning evaluation
-
Memory evaluation
-
Verification evaluation
-
Latency and cost measurement
-
Load and stress testing
-
Ablation studies
-
Human evaluation
-
Regression testing
-
Reproducibility
The central rule is simple:
Do not claim improvement until the benchmark demonstrates improvement.
This turns ACAI from a collection of architectural ideas into a testable research program.
End of Chapter 13
Stay tuned for Chapter: 14 Complete End-to-End System Architecture.
🚀 Connect with Black Shadow Team Across the Web! 🌐
We are actively sharing our latest cybersecurity research, AI safety insights, ethical hacking content, and tech updates across multiple platforms. Follow and subscribe to stay updated with our official channels:
📝 Articles & Research Papers:
Medium: https://medium.com/@blackshadowteam.net
Substack: https://blackshadowteam.substack.com
Dev.to: https://dev.to/black_shadow_team
HackerNoon: https://hackernoon.com/u/black-shadow-team
Hashnode: https://hashnode.com/@black-shadow-team
Blogspot: https://black-shadow-team.blogspot.com/
💻 Code & Open Source:
GitHub: https://github.com/blackshadowteamnet-netizen
WordPress: https://profiles.wordpress.org/blackshadowteam
📱 Social Media & Updates:
X (Twitter): https://x.com/BlackShadoTeam
Facebook Page: https://www.facebook.com/profile.php?id=61591268330812
Facebook Profile: https://www.facebook.com/profile.php?id=100090580510673
Instagram: https://www.instagram.com/black_shadow_team_x/
Threads: https://www.threads.net/@blacky_mahin_x
Bluesky: https://bsky.app/profile/black-shadow-team.bsky.social
💬 Community & Discussions:
Reddit: https://www.reddit.com/user/blackshadowteamoffic/
Quora (Bangla): https://bn.quora.com/profile/Black-Shadow-Team
Mix: https://mix.com/black_shadow_team
Discord: https://discord.com/channels/1518981404074184725/1518981404632023143
🎵 Short Videos & Audio:
TikTok: https://www.tiktok.com/@blackshadowteam.net
SoundCloud: https://on.soundcloud.com/VBWtOYsgktkw37kAza
Goodreads: https://www.goodreads.com/user/show/203582586-black-shadow-team-team
Stay connected and join our growing cybersecurity community! 🛡️✨



Comments
Post a Comment