16.1 Introduction
The previous chapters described the architecture, implementation, infrastructure, evaluation methodology, security model, and deployment roadmap of ACAI.
This chapter focuses on the research question:
What could ACAI contribute to AI-system research, what are its limitations, and what experiments would be necessary to establish its value?
An important distinction must be maintained throughout this chapter:
ACAI is a proposed architecture and research program. The contributions described below are potential contributions, not experimentally proven discoveries.
16.2 Potential Research Contribution 1 — Modular Cognitive Orchestration
The first potential contribution is a modular architecture in which different cognitive functions are separated into independently testable components.
Instead of treating an AI application as:
ACAI treats the system as a collection of cooperating computational processes.
The research question is whether this modularity produces measurable improvements on complex tasks.
16.3 Potential Research Contribution 2 — Adaptive Model Selection
A second potential contribution is dynamic model routing.
Instead of sending every request to the same model:
ACAI proposes:
The hypothesis is that specialized routing may provide a better quality–latency–cost tradeoff than using one model for every task.
16.4 Potential Research Contribution 3 — Adaptive Memory
Another proposed contribution is memory that is selective rather than simply storing every interaction.
The system could distinguish between:
The research challenge is determining whether this improves long-running tasks without introducing harmful stale or incorrect information.
16.5 Potential Research Contribution 4 — Verification as an Independent Layer
ACAI separates generation from verification.
This creates an experimentally testable question:
Does an additional verification layer reduce measurable errors sufficiently to justify its latency and computational cost?
The answer must come from experiments.
16.6 Potential Research Contribution 5 — Evaluation-Driven Architecture
Another important contribution is methodological rather than purely architectural.
Every major component can be evaluated independently.
This allows researchers to determine which components actually matter.
16.7 Potential Research Contribution 6 — Evidence-Based Complexity
A central principle of the proposal is:
Architectural complexity should be justified by measurable improvement.
For example:
This avoids the assumption that adding more agents, models, memory, or tools automatically creates a better AI system.
16.8 Research Contribution vs Research Claim
It is important to distinguish between:
Architecture
What the system proposes.
Hypothesis
What the researchers expect might happen.
Experiment
How the hypothesis will be tested.
Result
What the experiment actually demonstrates.
Claim
What can reasonably be concluded from the result.
For example:
is a hypothesis.
Whereas:
is an experimental claim that requires actual data.
16.9 Major Limitation — System Complexity
The first major limitation is architectural complexity.
A single-model application may look like:
ACAI may contain:
Every additional component creates:
-
More code
-
More failure modes
-
More monitoring requirements
-
More latency
-
More infrastructure
Therefore, complexity itself must be treated as a measurable cost.
16.10 Limitation — Latency
Multiple stages may increase response time.
For example:
may take longer than:
Therefore ACAI may be more appropriate for tasks where quality is more important than minimum latency.
16.11 Limitation — Computational Cost
Multiple model calls can increase resource consumption.
A system might theoretically improve task performance while becoming substantially more expensive.
Therefore evaluation should consider:
rather than accuracy alone.
16.12 Limitation — Memory Errors
Persistent memory introduces a new failure mode.
Suppose the system stores:
and later retrieves it as though it were true.
Then memory can amplify an original error.
Therefore memory requires:
-
Source tracking
-
Importance scoring
-
Update mechanisms
-
Expiration where appropriate
-
User controls
-
Validation
16.13 Limitation — Retrieval Errors
Retrieval systems can fail in several ways.
or:
The model may then produce a poor answer despite having a strong underlying language capability.
16.14 Limitation — Verification Is Not Perfect
A verifier is itself an AI or software system and can make mistakes.
Therefore:
Verification should therefore be treated as an additional defense layer, not as an absolute guarantee of correctness.
16.15 Limitation — Model Dependence
ACAI may still depend heavily on underlying foundation models.
If the underlying model is weak at a particular task, orchestration may not completely solve the problem.
Therefore:
System architecture and model capability are complementary rather than interchangeable.
16.16 Limitation — Evaluation Difficulty
Some AI capabilities are difficult to measure objectively.
For example:
-
Creativity
-
Helpfulness
-
Research quality
-
Explanation quality
-
Long-term usefulness
Automated metrics may not capture all of these dimensions.
Human evaluation therefore remains important for selected tasks.
16.17 Limitation — Benchmark Contamination
Modern models may have encountered publicly available benchmark questions during training.
Therefore benchmark results can sometimes overestimate generalization.
A strong evaluation program should use:
-
Carefully controlled datasets
-
Fresh evaluation tasks where possible
-
Private test sets
-
Multiple task categories
16.18 Limitation — Distribution Shift
A system tested on one dataset may behave differently in real-world conditions.
Therefore production monitoring is necessary after deployment.
16.19 Limitation — Multi-Agent Coordination
If multiple agents are introduced, they may disagree.
The coordinator must determine which result is appropriate.
This creates another research problem:
How should disagreement between specialized agents be resolved?
16.20 Limitation — Tool Reliability
AI systems using external tools inherit the reliability limitations of those tools.
For example:
or:
Therefore tool outputs should be validated and their provenance tracked.
16.21 Limitation — Security Surface
Every additional capability can expand the attack surface.
Therefore the architecture must balance capability with security.
16.22 Future Work — Better Planning
Future research could investigate more efficient planning mechanisms.
Potential research questions:
-
When is planning actually useful?
-
How much planning is enough?
-
Can simple tasks bypass planning?
-
Can planning depth adapt to task complexity?
A future architecture could dynamically choose:
while:
This could reduce unnecessary computation.
16.23 Future Work — Memory Optimization
Future versions could explore:
to decide what information should persist.
A memory system could potentially learn which information is useful without retaining everything.
16.24 Future Work — Efficient Routing
Model routing could become more sophisticated.
Instead of:
the router could consider:
The router could then choose the most appropriate available configuration.
16.25 Future Work — Self-Evaluation
A future system could automatically identify uncertain outputs.
However, such self-evaluation must itself be benchmarked to determine whether it actually improves outcomes.
16.26 Future Work — Continuous Benchmarking
The evaluation system could run automatically.
This would make evaluation a normal part of software development.
16.27 Future Work — Personalized System Behavior
If appropriate privacy controls are implemented, ACAI could adapt to user-specific workflows.
For example:
This should remain subject to explicit user controls and appropriate data-retention policies.
16.28 Future Work — Multimodal Architecture
The architecture could eventually support multiple modalities.
A multimodal pipeline could look like:
The same evaluation principles would still apply.
16.29 Future Work — Local + Cloud Models
A hybrid deployment could combine local and cloud models.
Local models may be useful for:
-
Privacy-sensitive workloads
-
Offline processing
-
Lower-cost repeated tasks
Cloud models may be useful when:
-
Higher capability is required
-
Large context is needed
-
Specialized models are unavailable locally
The correct choice should be determined by measured requirements.
16.30 Future Work — Specialized Agents
Future versions may explore specialized workers:
But specialization should be introduced only where experiments show a benefit.
A system with five agents is not automatically better than one with two.
16.31 Future Work — Formal Evaluation of Emergent Behavior
If the architecture eventually demonstrates unexpected capabilities, researchers should investigate them systematically.
The procedure should be:
This is more reliable than simply describing an impressive single example.
16.32 Future Work — Open Research Platform
If the project becomes sufficiently mature, a public research framework could expose standardized interfaces:
Researchers could then substitute different implementations.
For example:
and compare them under the same benchmark.
This could make architectural experiments more reproducible.
16.33 Potential Research Paper Structure
The complete project could eventually be written as a research paper with:
The final paper should report actual experimental results rather than hypothetical numbers.
16.34 What Would Make the Work Strong?
The research would become significantly stronger if it demonstrated:
The strongest contribution would not necessarily be the number of components.
It would be clear evidence that a particular architectural combination provides a measurable advantage under defined conditions.
16.35 What Would Not Be Sufficient Evidence?
The following would not, by themselves, prove the architecture is superior:
A research claim requires reproducible evidence.
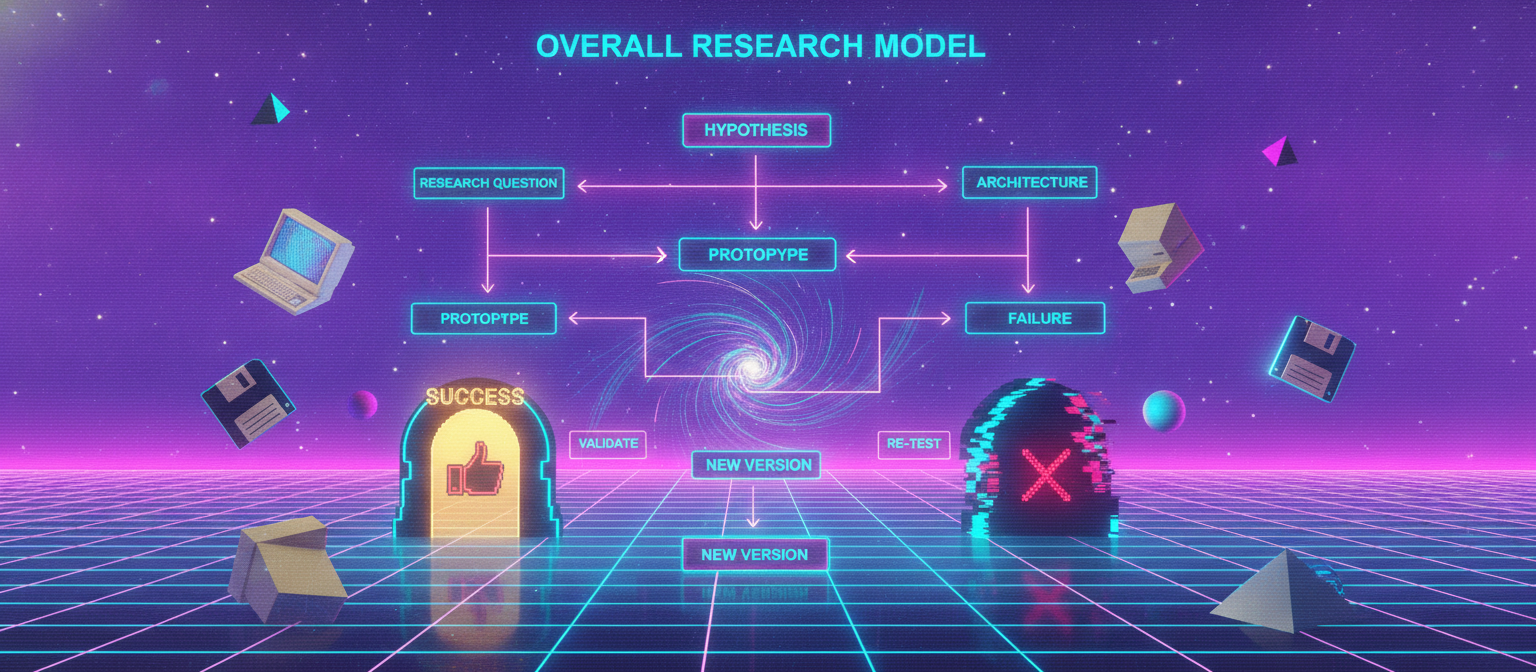
16.36 Overall Research Model
The entire research program can be represented as:
This creates a scientifically grounded development loop.
16.37 Final Research Position
ACAI should therefore be presented carefully.
A defensible description is:
ACAI is a proposed modular architecture for constructing advanced AI applications through coordinated planning, memory, retrieval, model selection, tool use, verification, and continuous evaluation. Its effectiveness remains an empirical question to be tested against appropriate baselines.
That wording is stronger scientifically than claiming that the architecture has already achieved superior intelligence.
16.38 Chapter Summary
This chapter identified potential contributions, limitations, and future research directions for ACAI.
The strongest potential contribution is not simply the existence of multiple AI components. It is the possibility of establishing a measurable relationship between system architecture and task performance.
The most important future direction is therefore empirical:
If the experiments demonstrate meaningful and reproducible improvements, the work can support stronger research claims.
If they do not, the results can still reveal which architectural assumptions were incorrect and guide future system design.
That distinction between proposal, hypothesis, experiment, and evidence should remain central to the entire project.
End of Chapter 16
Final section remaining:
Final Chapter — Conclusion, References & Research Appendix.
Stay tuned for Chapter: 17 Complete End-to-End System Architecture.
🚀 Connect with Black Shadow Team Across the Web! 🌐
We are actively sharing our latest cybersecurity research, AI safety insights, ethical hacking content, and tech updates across multiple platforms. Follow and subscribe to stay updated with our official channels:
📝 Articles & Research Papers:
Medium: https://medium.com/@blackshadowteam.net
Substack: https://blackshadowteam.substack.com
Dev.to: https://dev.to/black_shadow_team
HackerNoon: https://hackernoon.com/u/black-shadow-team
Hashnode: https://hashnode.com/@black-shadow-team
Blogspot: https://black-shadow-team.blogspot.com/
💻 Code & Open Source:
GitHub: https://github.com/blackshadowteamnet-netizen
WordPress: https://profiles.wordpress.org/blackshadowteam
📱 Social Media & Updates:
X (Twitter): https://x.com/BlackShadoTeam
Facebook Page: https://www.facebook.com/profile.php?id=61591268330812
Facebook Profile: https://www.facebook.com/profile.php?id=100090580510673
Instagram: https://www.instagram.com/black_shadow_team_x/
Threads: https://www.threads.net/@blacky_mahin_x
Bluesky: https://bsky.app/profile/black-shadow-team.bsky.social
💬 Community & Discussions:
Reddit: https://www.reddit.com/user/blackshadowteamoffic/
Quora (Bangla): https://bn.quora.com/profile/Black-Shadow-Team
Mix: https://mix.com/black_shadow_team
Discord: https://discord.com/channels/1518981404074184725/1518981404632023143
🎵 Short Videos & Audio:
TikTok: https://www.tiktok.com/@blackshadowteam.net
SoundCloud: https://on.soundcloud.com/VBWtOYsgktkw37kAza
Goodreads: https://www.goodreads.com/user/show/203582586-black-shadow-team-team
Stay connected and join our growing cybersecurity community! 🛡️✨



Comments
Post a Comment