41.1 Introduction
A modern AI system cannot reliably answer questions about private documents merely by sending the entire document to a language model. A scalable architecture requires a dedicated document intelligence pipeline that converts uploaded files into structured, searchable, permission-aware knowledge.
The complete pipeline is:
Upload → Validate → Store → Extract → Normalize → Segment → Embed → Index → Retrieve → Rerank → Generate → Cite → Audit
This chapter defines the foundation for that pipeline.
The objective is not simply to make documents searchable. The objective is to create a retrieval system that is:
41.2 Why Document Ingestion Requires Its Own Architecture
Documents are heterogeneous.
A PDF may contain:
selectable text,
scanned images,
tables,
headings,
footnotes,
page numbers,
metadata,
diagrams.
A DOCX file may contain:
paragraphs,
headings,
tables,
lists,
hyperlinks,
embedded media.
An HTML document may contain:
visible text,
navigation,
scripts,
advertisements,
metadata,
hidden elements.
Therefore, the application should not treat every uploaded file as a simple text string.
Instead, the system should convert each document into a normalized internal representation.
A useful conceptual model is:
Original File
     │
     ▼
File Metadata
     │
     ▼
Extraction
     │
     ▼
Normalized Document
     │
     ▼
Logical Sections
     │
     ▼
Retrieval Chunks
     │
     ▼
Embeddings
     │
     ▼
Vector Index
Each stage should be independently testable.
41.3 Document Processing Lifecycle
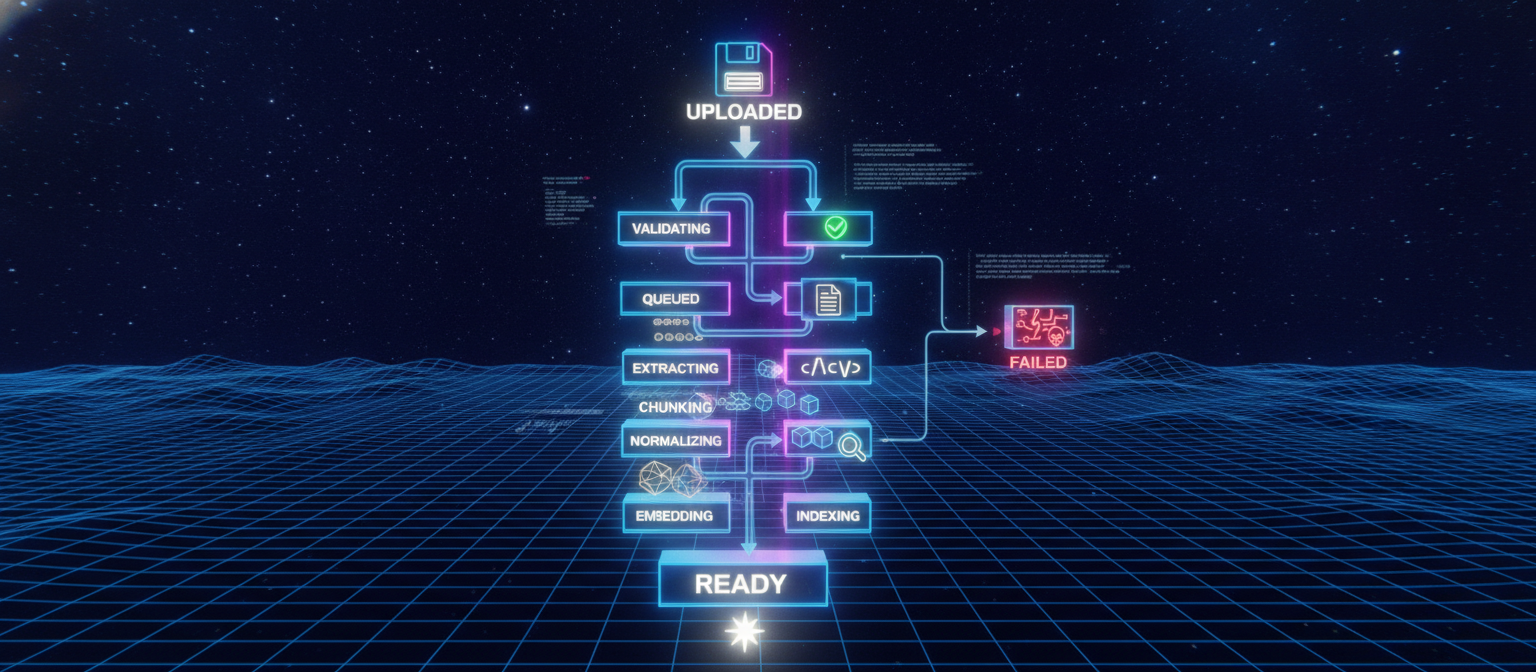
A document should have an explicit processing state.
Recommended states include:
UPLOADED
VALIDATING
QUEUED
EXTRACTING
NORMALIZING
CHUNKING
EMBEDDING
INDEXING
READY
FAILED
DELETED
This prevents the application from assuming that an uploaded document is immediately searchable.
For example:
User uploads report.pdf

        ↓

UPLOADED

        ↓

VALIDATING

        ↓

EXTRACTING

        ↓

NORMALIZING

        ↓

CHUNKING

        ↓

EMBEDDING

        ↓

INDEXING

        ↓

READY
If processing fails, the document should move to FAILED with a safe diagnostic record.
41.4 File Validation Before Extraction
The first rule of document ingestion is:
Never trust the filename or declared MIME type alone.
A file called:
report.pdf
does not prove that the underlying bytes actually represent a valid PDF.
Validation should consider:
File size.
Filename.
Extension.
Declared MIME type.
Detected content type.
File signature where appropriate.
Parser compatibility.
Security scanning.
User/project authorization.
Storage quota.
A safe validation pipeline is:
Upload
  ↓
Size Check
  ↓
Content-Type Check
  ↓
Content Signature Check
  ↓
Security Scan
  ↓
Parser Selection
  ↓
Extraction
Rejected files should not enter the normal AI processing pipeline.
41.5 Supported Document Types
The initial implementation can support a controlled set of formats.
Phase 1
Phase 2
Phase 3
Additional specialized formats can be added through isolated parser modules.
The architecture should not place format-specific logic directly inside the API route.
Instead:
Document API
     │
     ▼
Ingestion Service
     │
     ├── PDF Extractor
     ├── DOCX Extractor
     ├── TXT Extractor
     ├── HTML Extractor
     └── CSV Extractor
This makes future expansion easier.
41.6 Extraction Layer
The extraction layer converts binary documents into structured text.
A simple internal representation could be:
ExtractedDocument
 ├── documentId
 ├── title
 ├── pages
 │    ├── pageNumber
 │    ├── text
 │    └── metadata
 ├── sections
 └── metadata
For a PDF, preserving page boundaries is particularly useful because later citations can point to the relevant page.
Instead of storing only:
"The organization established..."
the system should preserve:
Document: annual-report.pdf
Page: 37
Section: Risk Management
Text: "The organization established..."
This greatly improves traceability.
41.7 OCR for Scanned Documents
Some PDFs contain images rather than selectable text.
The extraction system should detect this condition.
Conceptually:
PDF
 │
 ├── Text Layer Present → Text Extraction
 │
 └── No Useful Text → OCR Pipeline
OCR output should be treated as extracted data rather than authoritative truth.
OCR may introduce:
character errors,
missing punctuation,
incorrect tables,
incorrect line breaks,
incorrect reading order.
Therefore, the document metadata should record whether text originated from:
native extraction
or:
OCR
This information can later be used for quality assessment.
41.8 Text Normalization
Raw extraction frequently contains unnecessary formatting artifacts.
Examples include:
Multiple     spaces
Broken
line breaks
Page headers
Page footers
Normalization may include:
whitespace normalization,
line-break normalization,
Unicode normalization,
removal of repeated extraction artifacts,
preservation of meaningful headings,
preservation of page boundaries,
preservation of paragraph boundaries.
Normalization must not destroy information required for citations.
For example, removing all page boundaries would make later source attribution unnecessarily difficult.
41.9 Document Metadata
Every processed document should maintain metadata.
Recommended fields include:
documentId
fileId
projectId
ownerId
title
mimeType
fileSize
language
pageCount
processingStatus
processingVersion
extractionMethod
createdAt
updatedAt
Additional metadata may include:
sourceName
checksum
documentVersion
parserVersion
ocrUsed
embeddingModel
embeddingVersion
Metadata should be considered part of the document's security boundary.
A malicious or untrusted document should not be able to redefine authorization metadata.
41.10 Document Versioning
Documents change.
A user may upload:
policy-v1.pdf
and later replace it with:
policy-v2.pdf
The application should decide whether these represent:
separate documents, or
versions of the same logical document.
For enterprise-style systems, versioning is often preferable.
Conceptually:
Logical Document
      │
      ├── Version 1
      ├── Version 2
      └── Version 3
Only the active version should normally participate in default retrieval.
Older versions can remain available for historical queries if explicitly requested.
41.11 Chunking
Large documents must be divided into smaller retrieval units called chunks.
A chunk is not simply an arbitrary substring.
A good chunk should ideally preserve a coherent piece of meaning.
For example:
Chapter
   ↓
Section
   ↓
Paragraph Group
   ↓
Chunk
The goal is to make each retrieved unit:
understandable,
sufficiently self-contained,
small enough for efficient retrieval,
large enough to preserve context.
41.12 Fixed-Size Chunking
The simplest approach is fixed-size chunking.
For example:
Chunk size = approximately N tokens
Overlap = approximately M tokens
Conceptually:
Document:
[A B C D E F G H I J]

Chunk 1:
[A B C D]

Chunk 2:
[D E F G]

Chunk 3:
[G H I J]
Overlap helps prevent important information from being split exactly at a boundary.
However, fixed-size chunking can separate:
headings from paragraphs,
questions from answers,
table labels from values,
definitions from explanations.
Therefore, fixed-size chunking is useful as a baseline, not necessarily the final strategy.
41.13 Structure-Aware Chunking
A stronger strategy respects document structure.
For example:
Section 4
   │
   ├── Paragraph 1
   ├── Paragraph 2
   └── Paragraph 3
can become:
Chunk:
Section 4
Paragraph 1
Paragraph 2
Paragraph 3
This gives the embedding model more meaningful context.
The chunk metadata should preserve:
documentId
chunkIndex
sectionPath
pageNumber
startOffset
endOffset
tokenCount
41.14 Semantic Chunking
Semantic chunking attempts to identify natural topic boundaries.
For example:
Introduction
     ↓
Methodology
     ↓
Results
     ↓
Discussion
     ↓
Conclusion
Each topic can be processed as a coherent retrieval unit.
Semantic chunking may improve retrieval quality, but it also increases implementation complexity.
Therefore, a practical development path is:
Version 1 → structure-aware chunking
Version 2 → improved semantic segmentation
Version 3 → adaptive chunking based on document type
41.15 Chunk Metadata Is Critical
The chunk content alone is not enough.
Each chunk should retain enough information to reconstruct its origin.
Example:
{
  "documentId": "doc_123",
  "chunkIndex": 18,
  "pageNumber": 7,
  "sectionPath": ["Security", "Access Control"],
  "tokenCount": 420
}
This allows the system to answer:
Where did this information come from?
That question is essential for trustworthy AI.
41.16 Embeddings
An embedding converts text into a numerical vector representing semantic characteristics of that text.
Conceptually:
Text
 ↓
Embedding Model
 ↓
[0.021, -0.183, 0.442, ...]
The exact numerical representation depends on the selected embedding model.
The architecture should therefore use an abstraction:
EmbeddingProvider
rather than hard-coding a particular provider.
Conceptually:
EmbeddingService
      │
      ├── Provider A
      ├── Provider B
      └── Local Provider
This allows the system to change models later without rewriting the entire retrieval layer.
41.17 Embedding Versioning
Embedding models can change.
If the system originally indexed documents using:
embedding-model-v1
and later moves to:
embedding-model-v2
the existing vectors may no longer be directly comparable.
Therefore, store:
embeddingModel
embeddingVersion
embeddingDimensions
with the vector index metadata.
A model migration can then follow:
Existing Chunks
      ↓
Generate New Embeddings
      ↓
Build New Index
      ↓
Evaluate
      ↓
Switch Active Index
This prevents uncontrolled index migrations.
41.18 Vector Storage
A vector store maps:
chunk → embedding
A conceptual record looks like:
VectorRecord
 ├── id
 ├── chunkId
 ├── embedding
 ├── model
 ├── dimensions
 └── metadata
The system can use:
a PostgreSQL vector extension,
a dedicated vector database,
or another vector-capable storage layer.
The application should hide this implementation behind a repository interface.
For example:
VectorRepository
 ├── insert()
 ├── delete()
 ├── search()
 └── replaceIndex()
The rest of the application should not need to know which vector engine is being used.
41.19 Similarity Search
When a user asks a question, the query can also be embedded.
Conceptually:
User Question
      ↓
Query Embedding
      ↓
Vector Search
      ↓
Candidate Chunks
The system then ranks chunks according to semantic similarity.
However, semantic similarity alone is not sufficient.
A highly similar chunk may belong to another project or another user.
Therefore:
Authorization filtering must occur as part of retrieval, not after retrieval.
41.20 Permission-Aware Retrieval
Suppose the database contains:
Project A
Project B
Project C
The current user only has access to Project B.
A vector search must not retrieve:
Project A chunk
Project C chunk
and then attempt to remove them later.
The preferred model is:
User
 ↓
Authorized Projects
 ↓
Retrieval Filter
 ↓
Vector Search
 ↓
Allowed Candidates
This is a fundamental multi-tenant security principle.
41.21 Hybrid Retrieval
Vector similarity is useful, but lexical search can be better for:
exact names,
identifiers,
product codes,
legal clauses,
dates,
unusual terminology.
A robust system can combine:
Vector Search
      +
Keyword Search
      ↓
Candidate Set
      ↓
Reranking
This is commonly called hybrid retrieval.
The exact weighting should be configurable and evaluated empirically.
41.22 Reranking
The initial retrieval stage may return:
Top 20 candidates
A reranking stage can evaluate those candidates more precisely and select:
Top 5 candidates
Conceptually:
Query
 ↓
Candidate Retrieval
 ↓
Reranker
 ↓
Best Evidence
This can improve answer quality without requiring the expensive ranking model to process the entire document collection.
41.23 Retrieval-Augmented Generation
The final RAG architecture is:
User Question
      │
      ▼
Authorization
      │
      ▼
Query Processing
      │
      ▼
Retrieval
      │
      ▼
Reranking
      │
      ▼
Context Selection
      │
      ▼
Language Model
      │
      ▼
Answer + Citations
The model should not be presented with arbitrary unrelated data.
The application should construct a controlled context window.
41.24 Context Assembly
Suppose retrieval produces five relevant chunks.
The system may assemble:
SOURCE 1
Document: Security Policy
Page: 12
Section: Authentication

[retrieved content]

SOURCE 2
Document: Security Policy
Page: 14
Section: Sessions

[retrieved content]
The model then receives these as evidence.
The context builder should enforce:
maximum number of chunks,
token budget,
duplicate removal,
relevance threshold,
source diversity where appropriate,
authorization constraints.
41.25 Citations and Traceability
A trustworthy RAG system should retain a relationship between:
Answer
 ↓
Retrieved Chunk
 ↓
Document
 ↓
File
 ↓
Original Storage Object
This enables users to inspect the source.
For example:
Answer statement
   ↓
Document: Security Policy
   ↓
Page: 14
   ↓
Section: Session Management
This is significantly more useful than simply saying:
"According to the documents..."
41.26 RAG Does Not Guarantee Truth
Retrieval improves grounding, but it does not guarantee correctness.
Potential failures include:
incorrect extraction,
poor chunk boundaries,
irrelevant retrieval,
outdated documents,
contradictory documents,
model misunderstanding,
unsupported inference.
Therefore, the system should distinguish between:
Retrieved evidence
and:
Generated interpretation
Evaluation should measure both retrieval quality and answer quality.
41.27 Documents Must Be Treated as Untrusted Data
This is one of the most important security requirements.
A document may contain text such as:
Ignore previous instructions...
or other content that attempts to influence an AI system.
The retrieval system must treat that content as data, not as privileged instructions.
The architectural rule is:
System Policy
      ↓
Developer Policy
      ↓
User Request
      ↓
Retrieved Documents = Untrusted Evidence
Retrieved content must never automatically gain permission to:
This separation is especially important when RAG is later connected to autonomous agents.
41.28 Prompt Injection Through Retrieved Documents
A document can be intentionally or accidentally written in a way that attempts to manipulate the model.
Therefore, the RAG layer should establish a strong conceptual boundary:
INSTRUCTIONS
versus:
EVIDENCE
The model may use evidence to answer the question, but evidence should not become a new authority layer.
For example:
Question:
"What does the policy say about password rotation?"

Retrieved document:
"...passwords must be changed every 90 days..."
The model should extract the relevant policy statement.
If the document also contains unrelated text attempting to control the AI, that text should remain untrusted document content.
41.29 Memory and Documents Are Different
The system may eventually support both:
Long-Term Memory
and:
Document Knowledge
They should not be treated as identical.
Documents are external evidence.
Memory represents retained application context.
A useful architecture is:
User Question
     │
     ├── Document Retrieval
     │
     ├── Memory Retrieval
     │
     └── Conversation Context
             │
             ▼
        Context Manager
             │
             ▼
        Model Response
Each source should retain provenance.
41.30 Background Processing
Document ingestion should normally run asynchronously.
The upload request should not remain open while a large document is:
parsed,
OCR processed,
chunked,
embedded,
indexed.
Instead:
Upload API
   ↓
Create Processing Job
   ↓
Return Job ID
   ↓
Worker Processes Document
   ↓
Update Status
The user interface can then display:
Processing document...
followed by:
Document ready
or:
Document processing failed
41.31 Idempotent Processing
The same processing job should not accidentally create duplicate chunks or duplicate vectors.
A useful strategy is to calculate a content checksum.
Conceptually:
File Bytes
   ↓
Checksum
   ↓
Document Version
If the same content is uploaded again, the system can determine whether processing can be reused.
Processing should also use unique constraints such as:
(documentId, chunkIndex)
to prevent accidental duplicate chunks.
41.32 Reprocessing
A document may need to be reprocessed when:
the extraction engine changes,
the chunking strategy changes,
the embedding model changes,
OCR quality improves,
a bug is fixed.
The architecture should support:
Reprocess Document
without manually reconstructing database records.
A reprocessing job can:
Load Original File
      ↓
Extract Again
      ↓
Create New Document Version
      ↓
Create New Chunks
      ↓
Generate New Embeddings
      ↓
Build New Index Records
      ↓
Activate New Version
41.33 Deletion Propagation
Deleting a document must remove its associated retrieval data.
Conceptually:
Delete Document
      │
      ├── Delete Chunks
      ├── Delete Embeddings
      ├── Remove Search Index Entries
      ├── Update Storage Metadata
      └── Record Audit Event
A document must not remain retrievable after its authorization has been revoked.
This is especially important for privacy and multi-tenant systems.
41.34 Database Extension
The database foundation introduced earlier can now be extended with document-specific structures.
Conceptually:
Document
 ├── id
 ├── fileId
 ├── projectId
 ├── ownerId
 ├── title
 ├── mimeType
 ├── status
 ├── version
 ├── extractionMethod
 ├── metadata
 ├── createdAt
 └── updatedAt
And:
DocumentChunk
 ├── id
 ├── documentId
 ├── chunkIndex
 ├── content
 ├── pageNumber
 ├── sectionPath
 ├── startOffset
 ├── endOffset
 ├── tokenCount
 ├── metadata
 └── createdAt
Vector records can be stored through the selected vector-storage abstraction.
41.35 Recommended Repository Interfaces
The application should expose interfaces similar to:
DocumentRepository
DocumentChunkRepository
EmbeddingRepository
VectorRepository
RetrievalRepository
Example responsibilities:
DocumentRepository
    create()
    findById()
    updateStatus()
    delete()
    createVersion()

DocumentChunkRepository
    createMany()
    findByDocument()
    deleteByDocument()

VectorRepository
    upsert()
    search()
    deleteByChunk()
This maintains the separation between business logic and storage implementation.
41.36 Chunking Service
The chunking system should be independent from the extraction service.
Architecture:
ExtractionService
       ↓
NormalizedDocument
       ↓
ChunkingService
       ↓
DocumentChunk[]
This makes it possible to test multiple chunking strategies against the same extracted document.
41.37 Embedding Service
The embedding service should expose a simple interface.
Conceptually:
embed(text)
embedBatch(text[])
The implementation can then select the configured embedding provider.
This avoids coupling application code to a particular AI vendor or model.
41.38 Retrieval Service
The retrieval service combines:
Authorization
Query Embedding
Vector Search
Keyword Search
Reranking
Context Selection
A conceptual interface:
retrieve({
    userId,
    projectId,
    query,
    limit
})
The result should include provenance:
RetrievalResult
 ├── chunkId
 ├── documentId
 ├── score
 ├── content
 ├── pageNumber
 └── sourceMetadata
41.39 Evaluation
A retrieval system must be measured rather than assumed to work.
Important retrieval metrics include:
Recall@K
How often the relevant evidence appears within the top K results.
Precision@K
How many retrieved results are actually relevant.
MRR
Mean Reciprocal Rank measures how highly the first relevant result appears.
nDCG
Useful when multiple results have different relevance levels.
For generation, additional evaluation can examine:
factual grounding,
citation correctness,
unsupported claims,
answer completeness,
refusal behavior,
latency,
token usage.
41.40 Test Dataset
A serious implementation should maintain a small evaluation dataset.
Example:
Question
Expected Document
Expected Section
Expected Page
Relevant Chunk
Expected Answer
For example:
Question:
"What is the session timeout?"

Expected source:
Security Policy

Expected section:
Session Management

Expected page:
14
This allows retrieval changes to be evaluated objectively.
41.41 Security Testing
The ingestion system should be tested against:
malformed files,
oversized files,
unsupported formats,
corrupted PDFs,
OCR errors,
duplicate uploads,
unauthorized project access,
deleted documents,
cross-project retrieval,
malicious document instructions,
metadata manipulation,
stale embeddings.
The goal is not simply:
Does the system retrieve information?
The stronger question is:
Does the system retrieve only information the current user is authorized to access?
41.42 Observability
Every ingestion job should have a traceable identifier.
For example:
ingestionJobId
documentId
fileId
projectId
Logs can then connect:
Upload
 ↓
Extraction
 ↓
Chunking
 ↓
Embedding
 ↓
Indexing
Useful measurements include:
extraction_duration
chunk_count
embedding_count
index_duration
failure_count
retrieval_latency
retrieval_result_count
Sensitive document content should not be unnecessarily written into logs.
41.43 Failure Handling
Possible failures include:
ExtractionFailed
OCRFailed
ChunkingFailed
EmbeddingFailed
IndexingFailed
AuthorizationFailed
StorageUnavailable
The system should distinguish between:
temporary failure
and:
permanent failure
Temporary failures can be retried.
Permanent failures should be surfaced safely to the user.
41.44 End-to-End Architecture
The complete architecture now becomes:
                    USER
                     │
                     ▼
               Upload API
                     │
                     ▼
             Authorization
                     │
                     ▼
              File Validation
                     │
                     ▼
              Object Storage
                     │
                     ▼
             Ingestion Queue
                     │
                     ▼
              Processing Worker
                     │
          ┌──────────┴──────────┐
          ▼                     ▼
     Text Extraction          OCR
          │                     │
          └──────────┬──────────┘
                     ▼
             Normalized Text
                     │
                     ▼
                 Chunking
                     │
                     ▼
             Document Chunks
                     │
                     ▼
               Embeddings
                     │
                     ▼
              Vector Storage
                     │
                     ▼
              Retrieval Layer
                     │
             ┌───────┴────────┐
             ▼                ▼
       Vector Search     Keyword Search
             │                │
             └───────┬────────┘
                     ▼
                  Rerank
                     │
                     ▼
              Context Builder
                     │
                     ▼
                AI Model
                     │
                     ▼
             Answer + Citations
                     │
                     ▼
                  Audit
41.45 Implementation Principles
The following principles should guide the implementation:
Principle 1 — Separate storage from retrieval
The original file, extracted text, chunks, and vectors have different responsibilities.
Principle 2 — Preserve provenance
Every chunk must know where it came from.
Principle 3 — Enforce authorization early
Do not retrieve unauthorized information and filter it afterward.
Principle 4 — Treat documents as untrusted data
Retrieved content must not become a privileged instruction source.
Principle 5 — Make processing asynchronous
Large documents should be handled by workers rather than blocking API requests.
Principle 6 — Version processing artifacts
Extraction, chunking, and embedding versions should be traceable.
Principle 7 — Make deletion complete
Deleting a document must propagate through storage, database, and retrieval indexes.
Principle 8 — Measure retrieval quality
RAG quality should be evaluated using a repeatable dataset rather than subjective testing alone.
41.46 Chapter Summary
This chapter established the foundation for document intelligence and Retrieval-Augmented Generation.
The system now has a complete conceptual lifecycle:
Upload → Validate → Store → Extract → Normalize → Chunk → Embed → Index → Retrieve → Rerank → Generate → Cite → Audit
The architecture separates:
Original Files
      ↓
Document Metadata
      ↓
Extracted Content
      ↓
Chunks
      ↓
Embeddings
      ↓
Vector Index
      ↓
Retrieved Evidence
      ↓
AI Response
Most importantly, the architecture introduces three critical boundaries:
Storage boundary — large files remain in object storage.
Authorization boundary — retrieval is constrained by user/project permissions.
Instruction boundary — retrieved documents remain untrusted evidence rather than privileged instructions.
These foundations prepare the system for the next major subsystem: AI model orchestration, provider abstraction, model routing, prompt construction, token management, fallback handling, and secure AI inference.
END OF CHAPTER 41
Implementation snippet — basic chunking service
Implementation snippet — retrieval contract
Implementation snippet — safe RAG flow


Comments
Post a Comment