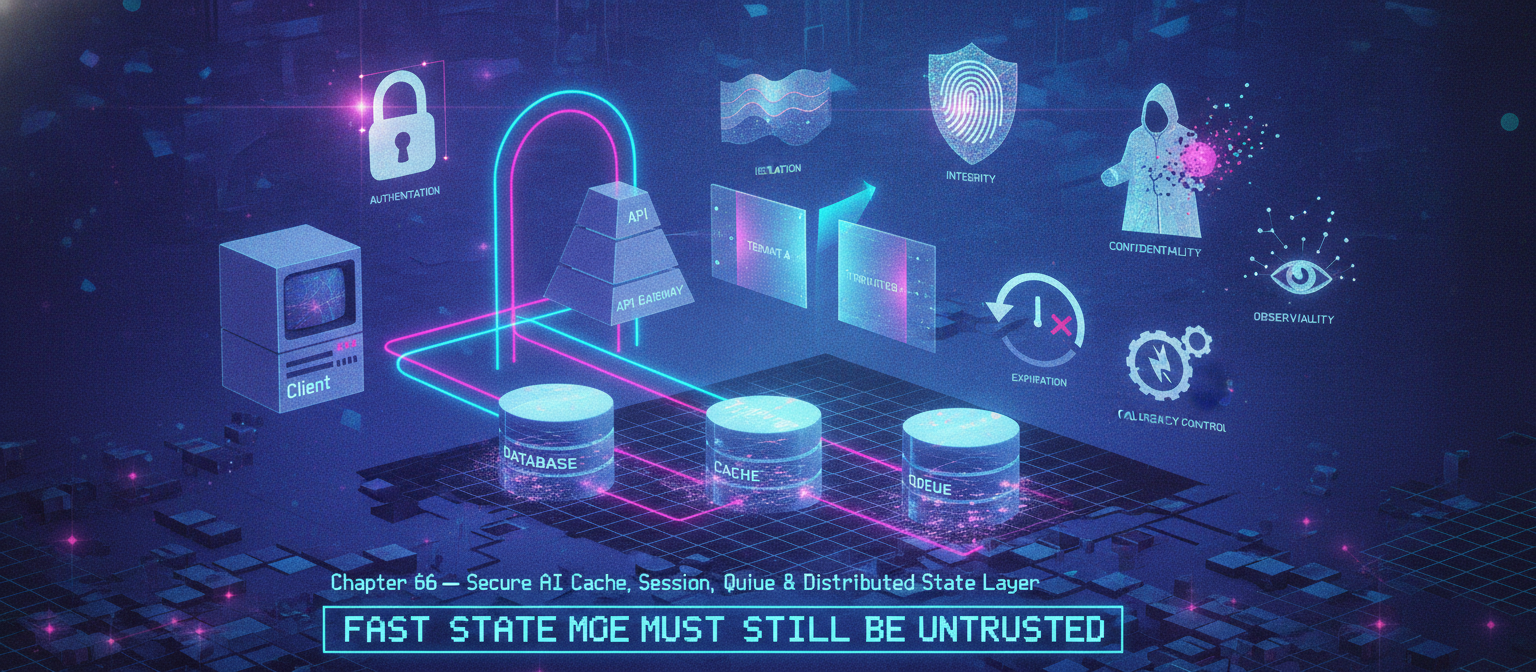
66.1 Introduction
Modern AI applications depend on distributed state.
A production AI platform may need to maintain:
user sessions
authentication state
rate-limit counters
temporary workflow state
job queues
distributed locks
cache entries
idempotency records
task progress
streaming state
notification state
short-lived AI inference context
provider-health information
feature flags
security decisions
temporary authorization state
A common technology for these workloads is an in-memory data platform such as Redis.
However, introducing a high-speed distributed state layer also introduces a new security boundary.
The central security principle is:
Fast state must still be treated as untrusted application state and protected according to its sensitivity.
A cache should not automatically become a source of truth.
A queue should not automatically be considered trusted.
A session record should not automatically authorize an operation.
A distributed lock should not automatically prove ownership.
A value stored in Redis should not automatically be trusted merely because an internal service wrote it.
The architecture therefore needs explicit controls for:
authentication
authorization
isolation
integrity
confidentiality
expiration
replay resistance
concurrency control
failure handling
observability
66.2 Role of a Distributed State Layer
A distributed state layer sits between application services and persistent infrastructure.
A simplified architecture is:
                    ┌─────────────────┐
                    │     Client      │
                    └────────┬────────┘
                             │
                             ▼
                    ┌─────────────────┐
                    │   API Gateway   │
                    └────────┬────────┘
                             │
                             ▼
                    ┌─────────────────┐
                    │ Application API │
                    └────────┬────────┘
                             │
                ┌────────────┼────────────┐
                │            │            │
                ▼            ▼            ▼
          ┌──────────┐ ┌──────────┐ ┌──────────┐
          │ Database │ │   Cache  │ │   Queue  │
          └──────────┘ └──────────┘ └──────────┘
The distributed state layer can reduce database load and coordinate asynchronous services.
But it can also become a high-impact target.
If an attacker gains unauthorized access to the state layer, consequences may include:
Therefore, Redis or another state platform should be treated as critical infrastructure rather than merely a performance component.
66.3 Cache Security
Caching is one of the most common uses of Redis.
Typical cached objects include:
user:{user_id}:profile
model:{model_id}:metadata
tenant:{tenant_id}:settings
permission:{user_id}:{resource}
provider:{provider_id}:health
generation:{generation_id}:status
The primary risk is cache confusion.
An application might assume:
cache hit = trusted value
That assumption is dangerous.
A safer model is:
cache hit
   ↓
validate structure
   ↓
validate ownership
   ↓
validate freshness
   ↓
validate authorization relevance
   ↓
use value
66.4 Cache Poisoning
Cache poisoning occurs when incorrect or attacker-controlled data enters a cache and is subsequently trusted by application components.
Potential causes include:
insufficient authorization before cache writes
predictable cache keys
tenant identifiers omitted from keys
user-controlled cache keys
stale authorization data
compromised internal service
unsafe deserialization
incorrect invalidation
race conditions
For example, an unsafe design could use:
profile:{username}
If usernames are not globally unique or canonicalized correctly, multiple users could interact with the same cache namespace.
A safer design is:
tenant:{tenant_id}:user:{user_id}:profile
The application should preferably construct the key from trusted identity information rather than allowing arbitrary client-provided strings to define the namespace.
66.5 Tenant Isolation
Multi-tenant AI systems require strong cache isolation.
A useful conceptual model is:
Tenant A
 ├── users
 ├── sessions
 ├── jobs
 └── cache

Tenant B
 ├── users
 ├── sessions
 ├── jobs
 └── cache
Keys should encode the relevant security boundary.
For example:
tenant:{tenant_id}:session:{session_id}
tenant:{tenant_id}:job:{job_id}
tenant:{tenant_id}:rate:{user_id}
The application should still perform authorization checks.
A tenant identifier inside a key is not itself an authorization mechanism.
66.6 Session Security
Session state is more sensitive than ordinary cache data.
A session may contain:
A conceptual session record might look like:
{
  "session_id": "opaque-session-id",
  "user_id": "user-123",
  "tenant_id": "tenant-456",
  "created_at": 1780000000,
  "expires_at": 1780003600,
  "security_version": 4
}
Sensitive authentication material should not be unnecessarily stored in plaintext.
The session identifier should be:
66.7 Session Expiration
Every session needs an explicit lifetime.
Important concepts include:
Absolute lifetime
The session expires after a fixed maximum period.
Idle lifetime
The session expires after inactivity.
Revocation
Security-sensitive events invalidate the session.
Examples:
password reset
account recovery
suspected compromise
administrator revocation
security-policy change
A useful model is:
valid =
    authenticated
    AND not_expired
    AND not_revoked
    AND security_version_current
66.8 Session Fixation Defense
Session identifiers should be rotated after significant authentication transitions.
For example:
anonymous session
       ↓
login
       ↓
new authenticated session ID
Do not simply upgrade an existing attacker-known session identifier into an authenticated session.
66.9 Logout
Logout should not merely delete a browser cookie.
The server-side session should also become invalid.
Possible flow:
Logout
  ↓
invalidate session
  ↓
revoke refresh capability
  ↓
clear client state
  ↓
record security event
For high-risk applications, session revocation may also be linked to a user-level security version.
66.10 Cache TTL
Every temporary cache entry should have an appropriate TTL.
Example:
short-lived inference state → seconds/minutes
rate-limit state            → seconds/minutes
provider health             → seconds/minutes
temporary workflow state    → minutes/hours
long-lived metadata         → persistent database
The exact duration should depend on the data and security requirements.
TTL reduces:
stale state
memory consumption
accidental retention
exposure window
But TTL is not a substitute for explicit deletion.
66.11 Sensitive Data in Cache
Avoid placing unnecessary sensitive information in a general-purpose cache.
Examples that should receive special consideration:
A useful principle is:
If the application does not need a piece of information in memory, do not cache it.
66.12 Encryption
Distributed state infrastructure should use encryption in transit.
Typical architecture:
Application
     │
   TLS
     │
     ▼
 Redis / State Cluster
Encryption at rest should also be considered depending on the deployment environment and sensitivity of stored information.
Network-level isolation remains important even when encryption is enabled.
66.13 Redis Authentication and Authorization
Redis should never be exposed directly to the public Internet.
Preferred architecture:
Internet
   │
   ▼
API Gateway
   │
   ▼
Application Network
   │
   ▼
Private Redis Network
Only authorized application services should be able to connect.
Credential management should use a secrets-management system rather than hardcoded credentials.
66.14 Least-Privilege Service Access
Different services should ideally have different access requirements.
For example:
API Service
 ├── session read/write
 └── rate-limit state

Worker Service
 ├── queue operations
 └── job state

Analytics Service
 └── limited metrics access
A service that only needs queue access should not automatically receive unrestricted access to every session.
This reduces blast radius if one service is compromised.
66.15 Distributed Locks
Distributed locks are useful when multiple workers may attempt the same operation.
Example:
Worker A ──┐
           │
           ▼
       distributed
          lock
           ▲
           │
Worker B ──┘
Potential applications include:
But distributed locks are subtle.
A lock should have:
unique ownership token
expiration
bounded lifetime
safe release semantics
66.16 Lock Ownership
Never release a distributed lock merely because the key exists.
Unsafe conceptual operation:
DELETE lock
A worker could accidentally delete another worker's lock.
A safer model is:
lock value = unique owner token

release:
    delete only if value == owner token
This prevents one worker from releasing a lock owned by another.
66.17 Lock Expiration
Locks should not live forever.
Suppose:
Worker A acquires lock
Worker A crashes
Without expiration:
lock remains forever
The job may become permanently blocked.
With bounded expiration:
Worker A crashes
      ↓
lock expires
      ↓
Worker B can recover
However, expiration creates another problem: the original worker may continue executing after its lock expires.
Therefore, long-running critical operations need additional ownership and fencing mechanisms where appropriate.
66.18 Fencing
A fencing token can help prevent stale workers from modifying protected resources.
Conceptually:
Worker A → token 101
Worker B → token 102
If Worker A becomes stale, the protected downstream system can reject operations carrying token 101 once token 102 has become authoritative.
This is especially useful for high-value distributed workflows where stale ownership could cause corruption.
66.19 Queue Security
Queues transport work between services.
Example:
API
 │
 ▼
Queue
 │
 ├── Worker A
 ├── Worker B
 └── Worker C
A queue message should not automatically be considered trusted simply because it originated from an internal service.
Messages should have:
66.20 Queue Message Validation
Workers should validate messages before execution.
Example conceptual schema:
{
  "version": 1,
  "message_id": "msg-123",
  "job_id": "job-456",
  "tenant_id": "tenant-789",
  "operation": "media.process",
  "created_at": 1780000000
}
The worker should validate:
schema
type
required fields
tenant
authorization context
expiration
job existence
job status
Never blindly execute arbitrary fields from a queue message.
66.21 Queue Poisoning
A malicious or corrupted message could cause:
A resilient architecture uses:
Main Queue
    │
    ▼
Worker
    │
    ├── success → complete
    │
    ├── transient failure → retry
    │
    └── repeated failure → dead-letter queue
66.22 Retry Security
Retries should be bounded.
A dangerous design is:
failure
 ↓
retry forever
 ↓
failure
 ↓
retry forever
This can create:
resource exhaustion
duplicate side effects
provider overload
queue congestion
Use:
maximum retry count
exponential backoff
jitter
dead-letter handling
idempotency
66.23 Idempotency
AI workflows often involve expensive or irreversible operations.
For example:
generate image
charge account
send notification
create export
A network retry should not accidentally perform the operation twice.
An idempotency key can represent:
tenant + user + request + operation
The system stores the result or operation state for a suitable period.
Conceptually:
request
  ↓
idempotency key
  ↓
already processed?
 ├── yes → return existing result
 └── no  → execute
66.24 Replay Defense
Attackers may capture valid requests or messages and attempt to replay them.
Useful defenses include:
For security-sensitive operations:
message accepted
      ↓
nonce recorded
      ↓
same nonce rejected
66.25 Rate-Limit State
Distributed rate limiting often uses shared state.
Example:
User
 ↓
API Gateway
 ↓
Rate-limit state
 ↓
Allow / Deny
The counter might conceptually represent:
tenant:user:endpoint:window
Security concerns include:
Rate limiting should be designed according to the threat model.
66.26 Fail-Open vs Fail-Closed
Suppose Redis becomes unavailable.
Should the API allow requests?
There is no universal answer.
For ordinary performance caching:
cache unavailable
      ↓
query database
For security-critical authorization state:
authorization state unavailable
      ↓
deny or require stronger verification
For rate limiting:
state unavailable
      ↓
policy-dependent behavior
The decision should be explicit rather than accidental.
66.27 Pub/Sub Security
Pub/Sub systems can distribute events.
Examples:
generation.completed
user.updated
security.session.revoked
model.health.changed
Consumers should validate event structure and origin.
Sensitive events should not contain unnecessary secrets.
A useful principle is:
Events should contain references to protected data rather than duplicating sensitive data whenever possible.
For example:
generation.completed
generation_id = 123
may be safer than publishing an entire private generation record.
66.28 Event Ordering
Distributed systems do not always guarantee global event ordering.
Therefore, consumers should avoid assuming:
event A always arrives before event B
unless the architecture explicitly guarantees it.
Use:
66.29 Memory Exhaustion
An in-memory system is vulnerable to memory exhaustion.
Potential causes:
Controls include:
maximum object size
maximum queue message size
TTL
rate limiting
memory limits
eviction policy
quota
backpressure
monitoring
66.30 Large AI Payloads
AI applications may attempt to put large prompts, documents, generated outputs, or media metadata into Redis.
This is usually undesirable.
Instead of:
Redis
 └── 200 MB media object
prefer:
Object Storage
 └── media object

Redis
 └── object ID + workflow metadata
This preserves the distinction between:
fast state
persistent data
large binary objects
66.31 Serialization Security
Unsafe deserialization can create severe security problems.
Avoid arbitrary object deserialization from untrusted state.
Prefer:
JSON
MessagePack
Protobuf
explicit schema
with strict validation.
The system should know exactly what types it expects.
66.32 Cache Stampede
A cache stampede occurs when many requests simultaneously discover that the same cache entry has expired.
Example:
1000 requests
      ↓
cache miss
      ↓
1000 database requests
Defenses include:
request coalescing
single-flight mechanisms
jittered expiration
stale-while-revalidate
background refresh
These mechanisms should themselves be protected against lock abuse and starvation.
66.33 Cache Invalidation
One of the most difficult distributed-state problems is invalidation.
Suppose:
Database:
role = admin

Cache:
role = user
The application must determine which value is authoritative.
A strong architectural rule is:
Persistent authoritative state should remain authoritative; cache state should be disposable and reconstructable.
When critical data changes:
Database update
      ↓
transaction/event
      ↓
cache invalidation
66.34 Authorization Cache Risks
Caching authorization decisions can improve performance but introduces security risk.
Example:
User loses permission
      ↓
Database updated
      ↓
Old authorization decision remains cached
The user may temporarily retain access.
For high-risk permissions, consider:
66.35 AI Agent State
AI agents frequently require temporary state:
Agent
 ├── task
 ├── plan
 ├── tool results
 ├── approval state
 ├── retry count
 └── execution status
This state should be treated as security-sensitive.
An attacker who modifies:
approval = true
could potentially bypass a human approval boundary.
Therefore:
Security decisions must not rely solely on mutable cache state.
Critical authorization decisions should be anchored to an authoritative security layer.
66.36 Workflow State Integrity
A secure workflow should use explicit state transitions.
Example:
CREATED
   ↓
VALIDATED
   ↓
APPROVAL_REQUIRED
   ↓
APPROVED
   ↓
RUNNING
   ↓
COMPLETED
Invalid transitions should be rejected.
For example:
CREATED → COMPLETED
may be prohibited unless the workflow explicitly permits it.
This prevents simple state manipulation from bypassing workflow controls.
66.37 Security Versioning
A useful pattern is a security version associated with a user or tenant.
Example:
user security_version = 7
Session:
session security_version = 6
The application detects:
6 != 7
and invalidates the session.
This provides a practical mechanism for broad revocation.
66.38 Secrets and Distributed State
Secrets should not be casually stored in Redis.
If a secret must temporarily exist in memory:
Do not use Redis as a replacement for a proper secrets manager.
66.39 Logging
State-layer logging should capture security-relevant metadata without exposing sensitive values.
Useful fields include:
timestamp
service
operation
tenant_id
resource_id
request_id
actor_id
result
latency
error_code
Avoid logging:
passwords
session tokens
API keys
private content
encryption keys
full sensitive payloads
66.40 Monitoring
Important metrics include:
Cache
hit rate
miss rate
eviction count
memory usage
key count
large-value frequency
Queue
queue depth
processing latency
retry count
dead-letter count
oldest message age
Locks
acquisition failures
lock duration
expired locks
contention
Sessions
66.41 Security Alerts
Potential alerts include:
unexpected Redis exposure
authentication failures
abnormal key creation
memory exhaustion
mass session creation
mass session revocation
queue flooding
dead-letter spike
lock contention spike
cross-tenant access anomaly
unusual cache writes
Monitoring should focus on behavior rather than merely infrastructure availability.
66.42 Network Segmentation
A production deployment should isolate state infrastructure.
Example:
                 Internet
                    │
                    ▼
              Load Balancer
                    │
                    ▼
              API Subnet
                    │
          ┌─────────┴─────────┐
          ▼                   ▼
      App Services        Worker Services
          │                   │
          └─────────┬─────────┘
                    ▼
              State Subnet
             ┌──────┴──────┐
             ▼             ▼
           Redis         Queue
Only explicitly authorized network paths should exist.
66.43 Availability and Resilience
The state layer may become a critical dependency.
Production design should consider:
But availability should never be achieved by weakening security boundaries.
66.44 Backup Security
If state data is backed up, the backup becomes another security boundary.
Protect:
backup storage
encryption keys
backup credentials
restore procedures
access logs
retention policies
A deleted session or sensitive state should not remain indefinitely in uncontrolled backups unless retention requirements justify it.
66.45 Data Classification
Not all state has equal sensitivity.
A practical classification could be:
| State | Sensitivity |
|---|
| UI cache | Low |
| Public metadata | Low |
| Provider health | Low/Medium |
| Rate-limit counters | Medium |
| Workflow state | Medium/High |
| User session | High |
| Authorization state | High |
| Authentication secrets | Critical |
| Payment secrets | Critical |
Controls should increase with sensitivity.
66.46 Secure Key Design
Good keys should be:
Avoid accepting raw user strings as unrestricted Redis keys.
Instead:
application-generated namespace
+
trusted identifier
+
validated resource ID
66.47 Key Enumeration
Attackers should not be able to infer sensitive information simply by observing cache behavior.
Avoid meaningful secrets in key names.
Bad:
user:john@example.com:password-reset-token
Better:
auth:reset:{opaque_identifier}
The key itself should not unnecessarily reveal private information.
66.48 Cache Side Channels
Cache behavior can sometimes reveal whether a resource exists.
For example:
cache hit → faster response
cache miss → slower response
An attacker could attempt to infer:
account existence
resource existence
feature activation
membership
workflow status
Sensitive endpoints should normalize behavior where necessary.
66.49 Distributed State and Zero Trust
The state layer should fit the broader zero-trust architecture.
Instead of:
internal network = trusted
use:
service identity
+
authenticated connection
+
authorized operation
+
validated data
An internal service should not receive unlimited trust merely because it resides inside a private network.
66.50 Secure Architecture Pattern
A robust architecture can be represented as:
                    Client
                      │
                      ▼
                API Gateway
                      │
                Authentication
                      │
                Authorization
                      │
                      ▼
               Application Layer
                      │
        ┌─────────────┼─────────────┐
        ▼             ▼             ▼
    Database        Cache         Queue
        │             │             │
        │             │             ▼
        │             │          Workers
        │             │             │
        └─────────────┴─────────────┘
                      │
                Audit / Metrics
The important distinction is that each layer has a specific responsibility.
66.51 Recommended Separation of Responsibilities
Database
Authoritative persistent data.
Object storage
Large files and media.
Cache
Temporary derived state.
Queue
Asynchronous work delivery.
Session store
Short-lived authentication state.
Secrets manager
Secrets and credentials.
Audit system
Security and accountability records.
Observability platform
Metrics, logs and traces.
This separation reduces the chance that one infrastructure component becomes responsible for everything.
66.52 Secure AI Generation Workflow
A secure AI generation request might follow:
User Request
     ↓
Authentication
     ↓
Authorization
     ↓
Validation
     ↓
Idempotency Check
     ↓
Create Database Job
     ↓
Queue Message
     ↓
Worker
     ↓
Revalidate Job
     ↓
AI Provider
     ↓
Validate Output
     ↓
Object Storage
     ↓
Database Status Update
     ↓
Notification
Redis may assist with:
rate limiting
temporary state
locks
coordination
but should not become the authoritative source for every step.
66.53 Security Failure Scenario
Consider:
User submits generation request
       ↓
API creates job
       ↓
Queue receives job
       ↓
Worker starts processing
       ↓
Attacker modifies cached job state
       ↓
job.status = APPROVED
If the worker trusts the cache blindly, the attacker may bypass a security boundary.
A safer architecture is:
Worker
  ↓
load authoritative job
  ↓
verify approval
  ↓
verify tenant
  ↓
verify user authorization
  ↓
execute
The cache can accelerate lookup but should not silently redefine security policy.
66.54 Testing Strategy
Security testing should include:
Authentication tests
invalid credentials
expired sessions
revoked sessions
session fixation
session replay
Cache tests
tenant isolation
key collision
poisoning
stale authorization
TTL behavior
Queue tests
malformed messages
replay
duplicate jobs
unauthorized tenant
retry storms
Lock tests
expired locks
duplicate owners
stale workers
unsafe release
Resource tests
oversized values
queue flooding
memory exhaustion
excessive key creation
66.55 Threat Model
The state layer should be evaluated against:
| Threat | Control |
|---|
| Unauthorized Redis access | Network isolation + authentication |
| Cache poisoning | Validation + authorization |
| Cross-tenant leakage | Tenant-scoped keys + authorization |
| Session theft | Secure session design |
| Replay | TTL + nonce + idempotency |
| Queue poisoning | Schema + authorization |
| Infinite retries | Retry limits |
| Lock hijacking | Ownership tokens |
| Memory exhaustion | Quotas + limits |
| Stale authorization | Versioning + invalidation |
| Secret leakage | Minimize sensitive state |
| State tampering | Authoritative database checks |
66.56 Production Checklist
Before production:
[ ] Redis/state infrastructure is private
[ ] TLS is enabled where appropriate
[ ] Strong authentication is configured
[ ] Least-privilege access is enforced
[ ] Services have separate permissions
[ ] Tenant boundaries are explicit
[ ] Cache keys are canonicalized
[ ] User input cannot freely define namespaces
[ ] Sensitive data is minimized
[ ] TTLs are configured
[ ] Sessions have expiration
[ ] Sessions can be revoked
[ ] Security versions are supported where needed
[ ] Queue messages have schemas
[ ] Queue messages have IDs
[ ] Replay protection exists
[ ] Retries are bounded
[ ] Dead-letter handling exists
[ ] Locks have ownership tokens
[ ] Locks expire
[ ] Large media is kept out of Redis
[ ] Serialization is controlled
[ ] Memory limits exist
[ ] Rate limits exist
[ ] Monitoring is enabled
[ ] Security alerts are configured
[ ] Backups are protected
[ ] Recovery procedures are tested
[ ] State-layer access is audited
66.57 Final Architecture Principle
A secure AI application should never confuse speed with trust.
Redis, queues, caches, locks and temporary state can dramatically improve application performance and scalability.
But every piece of distributed state should have a clearly defined security role.
The most important architectural rule is:
Use distributed state to coordinate the system, not to accidentally become an uncontrolled security authority.
For a production AI platform, the preferred trust hierarchy is approximately:
Identity
   ↓
Authorization Policy
   ↓
Authoritative Persistent State
   ↓
Validated Workflow State
   ↓
Distributed Cache / Queue
   ↓
Temporary Derived Data
The lower layers can improve performance, but they should not silently override higher-level security decisions.
A secure state architecture therefore combines:
authentication + authorization + tenant isolation + TTL + validation + idempotency + replay defense + lock ownership + queue integrity + resource limits + observability + recovery.
That foundation becomes especially important when the same distributed state layer supports AI agents, asynchronous media processing, RAG workflows, billing events, notifications and autonomous task execution.
The next logical layer is:
Chapter 67 — Secure AI Networking & Service-to-Service Communication: TLS/mTLS, Service Identity, API-to-API Authentication, Network Segmentation, Service Mesh, DNS Security, Egress Control, Private Connectivity, Zero-Trust Networking, SSRF Defense & East-West Traffic Security.


Comments
Post a Comment