Chapter 92 — Secure AI Platform Threat Intelligence & Threat Modeling Operations
92.1 Introduction
A secure AI platform cannot rely only on vulnerability scanning, logging, monitoring, and incident response. Security teams also need to understand what can attack the platform, how attacks could occur, which assets are most valuable, and which defensive controls should receive priority.
This is the role of threat intelligence and threat modeling.
Threat modeling asks:
What could go wrong, how could it happen, what would be affected, and how can we reduce the risk?
Threat intelligence asks:
What threats are actually appearing in the environment or ecosystem, how are attackers behaving, and what defensive decisions should change as a result?
For AI systems, these disciplines become more complex because the attack surface includes not only traditional software and infrastructure but also:
A mature security program therefore combines:
Threat intelligence + threat modeling + detection engineering + vulnerability management + security architecture + incident response.
The objective is not to predict every possible attack.
The objective is to build a continuously updated understanding of risk so that security controls are applied where they provide the greatest defensive value.
92.2 Threat Intelligence vs Threat Modeling
These concepts are related but different.
Threat modeling
Threat modeling is primarily a forward-looking analysis.
It examines the system and asks:
What are our assets?
Who could attack them?
What trust boundaries exist?
What attack paths are possible?
What controls prevent or limit those attacks?
Threat intelligence
Threat intelligence is primarily an evidence-driven intelligence process.
It examines information about:
Threat actors
Campaigns
Vulnerabilities
Exploitation patterns
Malicious infrastructure
Attack techniques
Security incidents
Industry trends
Defensive observations
Threat intelligence helps answer:
What is happening?
Threat modeling helps answer:
What could happen to our architecture?
Together they create a stronger security decision process.
92.3 AI Platform Threat Landscape
A traditional web application may primarily focus on:
Authentication
Authorization
APIs
Databases
Servers
Networks
Files
Browsers
An AI platform contains all of these plus additional attack surfaces.
A simplified AI threat landscape is:
User
  |
  v
Frontend
  |
  v
API Gateway
  |
  +---- Authentication
  |
  +---- Policy Engine
  |
  v
AI Orchestrator
  |
  +---- Model Provider
  |
  +---- RAG
  |
  +---- Memory
  |
  +---- Tools
  |
  +---- Agents
  |
  +---- Media Processing
  |
  v
Databases / Storage / Queues
  |
  v
Infrastructure
Every boundary represents a potential security concern.
92.4 Critical AI Assets
Threat modeling begins with identifying assets.
Important AI assets may include:
Identity assets
User accounts
Sessions
Service identities
API credentials
Administrative accounts
Workload identities
Data assets
User documents
Images
Videos
Audio
Prompts
Conversation history
RAG documents
Vector embeddings
Memory
Training datasets
AI assets
Model weights
Model configurations
System prompts
Safety policies
Routing policies
Evaluation datasets
Fine-tuned models
Tokenizers
Guardrail configurations
Infrastructure assets
Kubernetes clusters
Containers
Databases
Object storage
Queues
Caches
CI/CD systems
Secrets managers
Network infrastructure
Business assets
Subscription information
Usage quotas
Billing records
Intellectual property
Customer relationships
Reputation
Threat modeling should prioritize assets based on impact, not merely technical complexity.
92.5 Asset Criticality Classification
A practical classification is:
| Level | Meaning |
|---|
| Critical | Compromise could cause catastrophic security or business impact |
| High | Significant confidentiality, integrity, availability, or financial impact |
| Medium | Limited but meaningful impact |
| Low | Minor impact |
For example:
Model weights
Potential impact:
RAG database
Potential impact:
Agent tool credentials
Potential impact:
Criticality should therefore consider both the asset itself and what an attacker could do through that asset.
92.6 Threat Actors
Threat intelligence should maintain a broad threat-actor model.
Potential categories include:
Opportunistic attackers
They target exposed systems with automated scanning and common attack techniques.
Financially motivated attackers
Their goals may include:
Fraud
Credential theft
Resource abuse
Account takeover
Cryptomining
API abuse
Data theft actors
Their objective is unauthorized access to:
Customer data
Documents
Personal information
Proprietary AI data
Insider threats
Potential sources include:
Supply-chain attackers
They may target:
Dependencies
Packages
Model repositories
Containers
Plugins
Build systems
CI/CD pipelines
AI-specific attackers
These attackers may deliberately target:
Prompt handling
Model behavior
Agent planning
Tool execution
RAG retrieval
Memory
AI safety mechanisms
Threat models should not assume that attackers interact only through the normal user interface.
92.7 Threat Actor Capability Model
Threat actors can also be classified by capability.
Low capability
Uses:
Public tools
Automated scanners
Known exploits
Basic credential attacks
Moderate capability
Can perform:
High capability
May possess:
Significant technical expertise
Custom tooling
Specialized infrastructure
Advanced persistence techniques
Supply-chain capabilities
The purpose of capability modeling is not to stereotype attackers.
It is to determine whether the security architecture can withstand increasingly capable adversaries.
92.8 AI-Specific Threat Categories
AI systems introduce several important threat categories.
92.8.1 Prompt Injection
Untrusted content attempts to influence the model's instructions.
Sources can include:
User input
Retrieved documents
Web pages
Uploaded files
Images
Tool responses
The primary security concern is not merely undesirable text.
The deeper concern is whether untrusted content can influence privileged operations.
92.9 Indirect Prompt Injection
An especially important scenario occurs when malicious instructions are embedded inside external content.
Example:
User
 |
 | "Summarize this document"
 v
Document
 |
 +-- malicious embedded instruction
 |
 v
RAG / AI system
If the model treats the document as an instruction rather than data, the attacker may influence downstream behavior.
Therefore:
Retrieved content must not automatically become trusted instructions.
92.10 Agent Threat Modeling
Agents require special attention because they can potentially take actions.
A useful threat model separates:
Perception
What information can the agent observe?
Reasoning
How does the agent decide what to do?
Planning
What sequence of actions can it construct?
Tool execution
Which tools can it call?
External effects
What changes can those tools make?
For example:
Prompt
  |
  v
Agent
  |
  v
Plan
  |
  +---- Search
  |
  +---- Database
  |
  +---- Email
  |
  +---- File system
  |
  +---- Payment
Each tool should have an explicit permission boundary.
92.11 Agent Attack Paths
Threat modeling should examine chains such as:
Untrusted Input
      |
      v
Prompt Injection
      |
      v
Agent Misinterpretation
      |
      v
Unauthorized Tool Selection
      |
      v
Sensitive Resource Access
      |
      v
Data Exposure
The most important lesson is:
AI security must analyze attack chains, not isolated prompts.
A prompt injection that cannot influence any privileged operation may have limited impact.
A prompt injection that can control a highly privileged tool represents a much greater risk.
92.12 RAG Threat Modeling
RAG introduces several attack surfaces.
Document ingestion
Threats include:
Malicious documents
Hidden instructions
Unsupported formats
Parser vulnerabilities
Malware
Poisoned information
Chunking
Potential issues include:
Context manipulation
Metadata loss
Tenant mixing
Embeddings
Potential concerns include:
Incorrect ownership
Unauthorized retrieval
Metadata leakage
Vector storage
Threats include:
Cross-tenant retrieval
Unauthorized search
Data deletion
Poisoned records
Retrieval
Threats include:
Generation
Threats include:
RAG therefore needs its own threat model rather than being treated as merely a database feature.
92.13 Memory Threat Modeling
Long-term AI memory creates another important security boundary.
Potential threats include:
Memory poisoning
Incorrect user association
Cross-user memory access
Sensitive information retention
Unauthorized memory modification
Malicious persistent instructions
Failure to delete memory
A memory system should therefore record:
Memory ID
Tenant ID
User ID
Source
Creation time
Classification
Purpose
Retention policy
Authorization policy
Integrity metadata
Memory must remain subject to normal data-governance and authorization controls.
92.14 Model Integrity Threats
Models are security-sensitive artifacts.
Potential threats include:
Tampered weights
Malicious model files
Unauthorized fine-tuning
Unapproved model replacement
Configuration manipulation
Backdoored artifacts
Unverified external models
A secure model lifecycle should therefore maintain:
Model
 |
 +-- Identity
 +-- Version
 +-- Source
 +-- Hash
 +-- Provenance
 +-- Evaluation status
 +-- Approval status
 +-- Deployment status
No production model should be trusted merely because it has a familiar filename.
92.15 AI Supply-Chain Threat Modeling
AI supply chains can contain:
Open-source packages
Model repositories
Dataset repositories
Container images
Plugins
Tokenizers
Evaluation libraries
External APIs
Cloud services
A supply-chain threat model should ask:
Who produced the component?
Where did it originate?
Was it modified?
How was it verified?
What permissions does it receive?
What happens if it becomes malicious?
Can it be replaced quickly?
This connects threat intelligence directly to supply-chain security.
92.16 Threat Intelligence Lifecycle
A mature threat intelligence lifecycle can be represented as:
Requirements
     |
     v
Collection
     |
     v
Processing
     |
     v
Analysis
     |
     v
Production
     |
     v
Dissemination
     |
     v
Feedback
     |
     +-------> Requirements
The lifecycle is continuous.
Threat intelligence should not become a static report stored in a folder.
92.17 Intelligence Requirements
Security teams should define what information they actually need.
Examples:
Which vulnerabilities affect our infrastructure?
Which attack techniques target AI applications?
Are our exposed services being actively targeted?
Which model supply-chain risks are emerging?
Are attackers abusing AI agents?
Which indicators should detection engineering monitor?
Which attack patterns should be included in red-team testing?
Without clear requirements, intelligence collection can become excessive but strategically useless.
92.18 Threat Intelligence Sources
Potential sources include:
Internal sources
Security incidents
SOC alerts
Authentication telemetry
Application logs
Vulnerability reports
Threat hunts
Red-team exercises
Abuse reports
External sources
External information should be evaluated for reliability before being treated as authoritative.
92.19 Intelligence Reliability
Not every threat report is equally trustworthy.
A simple model can evaluate:
Source reliability
How consistently has the source produced accurate information?
Information confidence
How strongly is the specific claim supported?
Relevance
Does it apply to our environment?
Timeliness
Is the information current?
Actionability
Can defenders actually use it?
This prevents security teams from reacting to every rumor or sensational security headline.
92.20 Threat Intelligence Enrichment
Raw indicators often have limited value.
Example:
IP address
By itself, it may not explain much.
Enrichment could provide:
IP
 |
 +-- Reputation
 +-- Hosting provider
 +-- Geography
 +-- Historical activity
 +-- Related domains
 +-- Related campaigns
 +-- Internal observations
The same principle applies to:
Domains
File hashes
User accounts
Model versions
API clients
Kubernetes workloads
AI providers
Context makes intelligence useful.
92.21 Threat Intelligence for AI Systems
AI security intelligence should monitor developments involving:
Prompt injection
Jailbreak techniques
Agent manipulation
RAG poisoning
Model extraction
Model integrity
Training-data poisoning
AI supply-chain attacks
Multimodal attacks
AI-generated phishing
Automated abuse
AI resource exhaustion
Safety-control bypasses
The purpose is defensive awareness.
Threat intelligence should feed:
Threat models
Security testing
Detection rules
SOC playbooks
Architecture decisions
Security policies
92.22 Threat Modeling Methodology
A repeatable threat-modeling process should include:
Step 1 — Define scope
Identify:
System
Components
Users
Data
Trust boundaries
External dependencies
Step 2 — Identify assets
Determine what must be protected.
Step 3 — Map data flows
Document:
Input
  |
  v
API
  |
  v
Service
  |
  +---- Database
  |
  +---- AI model
  |
  +---- Storage
  |
  v
Output
Step 4 — Identify threats
Consider:
Spoofing
Tampering
Repudiation
Information disclosure
Denial of service
Elevation of privilege
Then add AI-specific categories.
Step 5 — Identify attack paths
Determine how multiple weaknesses could combine.
Step 6 — Assess risk
Evaluate:
Likelihood × Impact
Step 7 — Select controls
Choose preventive, detective, and corrective controls.
Step 8 — Validate
Test whether controls actually work.
Step 9 — Maintain
Update the threat model as the architecture changes.
92.23 Trust Boundaries
Trust boundaries are among the most important parts of an AI threat model.
Typical boundaries include:
Internet
   |
   | Untrusted
   v
Frontend
   |
   | Authenticated
   v
API
   |
   | Authorized
   v
AI Orchestrator
   |
   +---- Model Provider
   |
   +---- RAG
   |
   +---- Tools
Every boundary should define:
Authentication
Authorization
Validation
Logging
Rate limiting
Data classification
Trust assumptions
92.24 Data-Flow Threat Modeling
Data-flow diagrams should identify:
Inputs
Outputs
Processing components
Storage
Trust boundaries
External systems
For AI platforms, also identify:
Prompt flow
Context flow
Retrieval flow
Tool-call flow
Model routing
Memory flow
Output flow
A threat model that ignores these flows may miss the most important AI-specific risks.
92.25 Attack Trees
Attack trees provide a structured way to analyze attack goals.
Example:
Goal:
Obtain another user's private document

                 OR
        +--------+--------+
        |                 |
   Compromise API    Abuse RAG
        |                 |
   +----+----+        +---+---+
   |         |        |       |
Auth flaw  IDOR     Poison  Retrieval
                     data   weakness
Attack trees help security teams identify multiple routes to the same business-impacting objective.
92.26 Attack Graphs
Attack graphs extend this concept into connected system paths.
For example:
Compromised Account
        |
        v
API Access
        |
        v
Weak Authorization
        |
        v
RAG Query
        |
        v
Cross-Tenant Retrieval
        |
        v
Sensitive Data Exposure
This demonstrates why individual controls should not be evaluated in isolation.
A seemingly low-risk weakness may become severe when combined with other weaknesses.
92.27 Risk Prioritization
Not every threat deserves equal engineering effort.
A practical risk model considers:
Risk =
Likelihood
× Impact
× Exposure
× Exploitability
× Business Criticality
Organizations can adapt the exact model to their environment.
The important principle is consistency.
92.28 AI Risk Dimensions
AI-specific risk assessment can additionally consider:
Model impact
What happens if the model behaves incorrectly?
Autonomy
Can the system take actions without human confirmation?
Data sensitivity
What information can the model access?
Tool privilege
What capabilities are exposed through tools?
External reach
Can the system interact with external services?
Persistence
Can malicious state survive across sessions?
Scale
Can one attack affect thousands of users?
Detectability
How easily can abuse be detected?
These dimensions help distinguish a harmless model-quality issue from a serious security vulnerability.
92.29 Threat Modeling Agents by Permission
A powerful security principle is:
Agent capability should never exceed the minimum capability required for the task.
For example:
Agent A
  |
  +-- Read public documents

Agent B
  |
  +-- Read user's documents

Agent C
  |
  +-- Modify user's project

Agent D
  |
  +-- External communication
These agents should not automatically share identical permissions.
Tool permissions should be explicit and enforceable outside the model.
92.30 Human Approval Boundaries
High-impact actions should often require human approval.
Examples include:
A secure architecture can use:
Agent
  |
  v
Proposed Action
  |
  v
Policy Engine
  |
  +---- Low Risk ---> Execute
  |
  +---- High Risk --> Human Approval
                         |
                         v
                      Execute
The model should not be the final authority over its own privileges.
92.31 Threat Intelligence → Detection Engineering
Threat intelligence becomes operationally valuable when translated into detections.
Example:
Threat Intelligence
        |
        v
Attack Technique
        |
        v
Detection Hypothesis
        |
        v
Telemetry Requirement
        |
        v
Detection Rule
        |
        v
SOC Alert
This creates a feedback loop between research and operations.
92.32 Threat Intelligence → Security Testing
Intelligence should also influence security testing.
If new research identifies a threat against:
RAG systems
Agents
Multimodal models
Model supply chains
the security testing program should consider whether equivalent scenarios should be tested in the organization's environment.
This creates:
Intelligence → Test Case → Evaluation → Control Improvement
92.33 Threat Intelligence → Architecture
Threat intelligence may also trigger architectural changes.
For example:
New Threat
   |
   v
Threat Assessment
   |
   v
Architecture Review
   |
   +---- Existing controls sufficient
   |
   +---- New control required
   |
   v
Engineering Change
   |
   v
Validation
Security intelligence should therefore reach architects and developers, not only SOC analysts.
92.34 Threat Modeling During Development
Threat modeling should occur before production.
Useful stages include:
Design phase
Identify fundamental risks.
Development phase
Review implementation-specific threats.
Pre-release phase
Validate controls.
Production phase
Monitor for changes in threat conditions.
Major architecture change
Rebuild the relevant threat model.
This is much more effective than creating one threat model once and never updating it.
92.35 Continuous Threat Modeling
AI systems change rapidly.
A platform may add:
Each change can modify the threat landscape.
Therefore:
Architecture Change
       |
       v
Threat Model Update
       |
       v
Risk Reassessment
       |
       v
Security Testing
       |
       v
Release Decision
Threat modeling should become part of engineering workflow.
92.36 Threat Model Versioning
Threat models should be version controlled.
Each version can contain:
Threat Model ID
System Version
Architecture Version
Date
Owner
Assets
Trust Boundaries
Threats
Risk Ratings
Controls
Open Risks
Approval Status
This provides historical traceability.
It also helps investigators determine which security assumptions existed when an incident occurred.
92.37 Threat Model Ownership
Threat modeling should have clear ownership.
Potential roles:
No single person needs to understand every component.
Cross-functional threat modeling is usually stronger.
92.38 Threat Intelligence Governance
Threat intelligence should have:
Sensitive intelligence may itself contain information that requires protection.
92.39 Threat Intelligence Security
Threat-intelligence systems can become targets.
An attacker might attempt to:
Therefore intelligence repositories require:
Authentication
Authorization
Integrity protection
Audit logging
Source provenance
Change tracking
Threat intelligence must itself be treated as security-sensitive data.
92.40 Threat Intelligence Poisoning
Security teams should distinguish between:
Known evidence
and:
Unverified claims.
An intelligence pipeline should preserve:
Source
Timestamp
Evidence
Confidence
Analysis
Attribution status
Related observations
This prevents unsupported conclusions from becoming operational facts.
92.41 Attribution Caution
Threat attribution is difficult.
A defensive program should avoid automatically claiming:
"Actor X definitely performed this attack."
unless sufficient evidence exists.
Instead, it may be more appropriate to state:
Observed technique
Observed infrastructure
Confidence level
Supporting evidence
Alternative explanations
This makes intelligence more defensible.
92.42 Threat Hunting Integration
Threat intelligence can produce hunting hypotheses.
Example:
Intelligence:
Attackers increasingly abuse unusual API behavior.

        |
        v

Hunting hypothesis:
Find sessions with abnormal API sequencing.

        |
        v

Search telemetry

        |
        v

Validate findings

        |
        v

Create detection if useful
This transforms intelligence into operational discovery.
92.43 Threat Intelligence and AI Abuse Detection
AI platforms should monitor for abuse patterns such as:
Unusual request volume
Rapid account creation
Credential reuse
Abnormal model switching
Excessive generation
Repeated policy-boundary testing
Unusual tool invocation
Abnormal document retrieval
Large-scale extraction behavior
Suspicious automation
These signals should be evaluated in context rather than relying on a single threshold.
92.44 Security Analytics Integration
Threat intelligence can enrich security analytics.
For example:
Authentication Event
        |
        +---- User risk
        |
        +---- Device context
        |
        +---- Threat intelligence
        |
        +---- Historical behavior
        |
        v
Risk Engine
        |
        v
Security Decision
This creates better detection than relying on isolated indicators.
92.45 Threat Intelligence Confidence
Security systems should distinguish:
Severity
from:
Confidence.
Example:
| Finding | Severity | Confidence |
|---|
| Possible abuse | High | Low |
| Confirmed exploit | High | High |
| Suspicious behavior | Medium | Medium |
| Known malicious artifact | High | High |
This prevents uncertain information from automatically triggering extreme responses.
92.46 Threat Prioritization Matrix
A practical matrix can classify threats:
| Likelihood | Impact | Priority |
|---|
| Low | Low | Low |
| High | Low | Medium |
| Low | High | Medium |
| High | High | Critical |
AI-specific factors can further increase priority:
High privilege
High scale
Sensitive data
Autonomous action
Difficult detection
External exposure
92.47 Threat Scenarios
Security teams should create realistic scenarios.
Example:
Scenario A — RAG data exposure
Attacker:
Obtains a valid account.
Manipulates retrieval queries.
Attempts to retrieve another tenant's information.
Exploits an authorization weakness.
Controls:
Scenario B — Agent tool abuse
Attacker:
Provides malicious input.
Attempts prompt manipulation.
Agent selects a privileged tool.
Policy engine blocks unauthorized action.
Controls:
Tool permissions
Policy enforcement
Human approval
Audit logging
Runtime monitoring
These scenarios can be turned into repeatable security tests.
92.48 Threat Scenario Library
A mature AI platform should maintain a threat-scenario library.
Categories may include:
Identity
API
Database
Storage
RAG
Memory
Models
Agents
Tools
Media
Supply Chain
Infrastructure
Payments
Administration
Insider
Availability
Privacy
Each scenario should include:
Threat description
Preconditions
Assets affected
Attack path
Expected controls
Detection signals
Response
Test status
Owner
92.49 Threat Model Quality Review
A threat model should be reviewed for:
Completeness
Were all important assets included?
Accuracy
Does the model represent the real architecture?
Assumption validity
Are trust assumptions still correct?
Control coverage
Does every important threat have appropriate controls?
Attack-path coverage
Were multi-step attacks considered?
AI-specific coverage
Were model, prompt, RAG, memory, and agent risks considered?
Operational coverage
Can SOC teams detect and respond to the scenario?
92.50 Common Threat Modeling Failures
Failure 1 — Static documents
A threat model is created once and forgotten.
Improvement
Integrate threat modeling with architecture and release processes.
Failure 2 — Only infrastructure threats
Teams model:
but ignore:
Prompts
Models
RAG
Agents
Memory
Improvement
Include AI-specific data and control flows.
Failure 3 — Treating the model as trusted
The model is allowed to decide what it is authorized to do.
Improvement
Enforce permissions outside the model.
Failure 4 — Indicator obsession
Teams collect thousands of indicators without understanding relevance.
Improvement
Prioritize intelligence that supports decisions.
Failure 5 — No attack chains
Threats are evaluated independently.
Improvement
Use attack trees and attack graphs.
Failure 6 — No operational validation
Controls exist on paper but are never tested.
Improvement
Connect threat models to security testing and detection validation.
92.51 AI Threat Modeling Checklist
Architecture
Assets
AI
Infrastructure
Operations
92.52 Threat Intelligence Checklist
92.53 Threat Intelligence Metrics
Useful metrics include:
Intelligence coverage
Percentage of relevant threat areas monitored.
Intelligence-to-detection conversion
How much useful intelligence becomes operational detection.
Time to intelligence
How quickly new information reaches defenders.
Time to action
How quickly intelligence produces a defensive change.
Detection improvement
Whether intelligence actually improves detection.
Threat-model coverage
Percentage of critical systems with current threat models.
Threat-model freshness
Average age of active threat models.
Scenario coverage
Percentage of important threats represented by tested scenarios.
Metrics should measure security outcomes, not simply document volume.
92.54 Threat Intelligence Maturity Model
Level 1 — Reactive
Ad hoc research
Manual reports
Limited threat modeling
Level 2 — Repeatable
Level 3 — Integrated
Intelligence feeds detection engineering
Threat models influence architecture
Security testing uses threat scenarios
Level 4 — Adaptive
Level 5 — Optimized
Intelligence, detection, architecture, testing, and response operate as a continuous security feedback loop.
92.55 Reference Secure AI Threat Intelligence Architecture
A mature architecture can be represented as:
              External Intelligence
                       |
                       v
              +------------------+
              | Intelligence     |
              | Processing       |
              +------------------+
                       |
                       v
              +------------------+
              | Threat Knowledge |
              | Repository       |
              +------------------+
                 /      |       \
                /       |        \
               v        v         v
        Threat Model  Detection  Hunting
             |          |          |
             v          v          v
       Architecture   SOC       Security Tests
             |          |          |
             +----------+----------+
                        |
                        v
                 Risk Decisions
                        |
                        v
                Security Controls
                        |
                        v
                 Production AI
                        |
                        v
                   Telemetry
                        |
                        +-----------> Intelligence
This creates a continuous defensive loop.
92.56 Threat Modeling and the Secure Development Lifecycle
Threat modeling should become part of the secure development lifecycle.
A practical process is:
Idea
 |
 v
Architecture
 |
 v
Threat Model
 |
 v
Security Requirements
 |
 v
Implementation
 |
 v
Security Testing
 |
 v
Release
 |
 v
Monitoring
 |
 v
Threat Intelligence
 |
 +----> Updated Threat Model
This means security is continuously informed by real-world evidence.
92.57 AI Threat Intelligence Feedback Loop
The most mature architecture creates a feedback loop:
Threat Intelligence
        |
        v
Threat Modeling
        |
        v
Security Requirements
        |
        v
Engineering Controls
        |
        v
Security Testing
        |
        v
Production
        |
        v
Telemetry
        |
        v
Detection
        |
        v
Incidents / Findings
        |
        +-----------> Threat Intelligence
This transforms security from a static checklist into an adaptive system.
92.58 Strategic Principles
Several principles should guide AI threat intelligence and modeling.
Principle 1
Model the whole system, not only the model.
Principle 2
Treat untrusted AI input as untrusted data.
Principle 3
Never let model output directly define authorization.
Principle 4
Analyze attack chains, not isolated weaknesses.
Principle 5
Connect intelligence to actual defensive decisions.
Principle 6
Track confidence separately from severity.
Principle 7
Continuously update threat models as architecture changes.
Principle 8
Prioritize high-impact, high-privilege attack paths.
Principle 9
Make security scenarios testable.
Principle 10
Use production telemetry to improve future threat models.
92.59 Final Secure AI Threat Intelligence Architecture
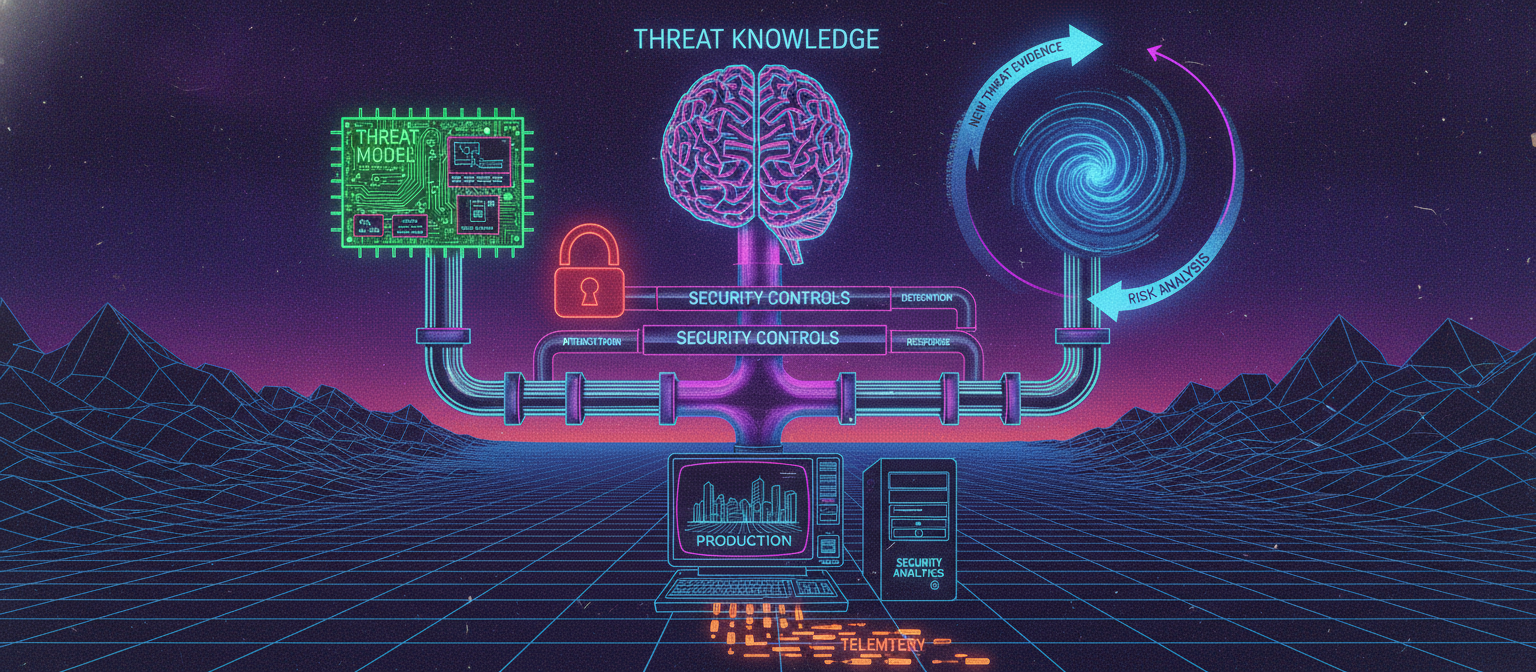
A complete mature model can be summarized as:
                 THREAT INTELLIGENCE
                         |
                         v
                 Threat Knowledge
                         |
                         v
                  THREAT MODEL
                         |
             +-----------+-----------+
             |           |           |
             v           v           v
          Assets      Attack       Trust
                      Paths       Boundaries
             |           |           |
             +-----------+-----------+
                         |
                         v
                   RISK ANALYSIS
                         |
                         v
                SECURITY CONTROLS
                         |
        +----------------+----------------+
        |                |                |
        v                v                v
   Prevention       Detection        Response
        |                |                |
        +----------------+----------------+
                         |
                         v
                    PRODUCTION
                         |
                         v
                     TELEMETRY
                         |
                         v
                  SECURITY ANALYTICS
                         |
                         v
                NEW THREAT EVIDENCE
                         |
                         +-----> INTELLIGENCE
This architecture provides a continuous security-learning loop.
92.60 Conclusion
Threat intelligence and threat modeling provide the strategic layer that connects the individual security controls of an AI platform.
Threat modeling identifies:
Assets
Trust boundaries
Threats
Attack paths
Security assumptions
Required controls
Threat intelligence provides:
For AI platforms, the scope must extend beyond traditional infrastructure.
Security teams must consider:
Models
Prompts
RAG
Memory
Agents
Tools
Data
Supply chains
Multimodal inputs
Autonomous actions
The most important architectural principle is:
A secure AI platform should continuously convert threat intelligence into threat models, threat models into security controls, security controls into tested defenses, and production evidence back into improved intelligence.
That continuous feedback loop is what allows an AI security program to evolve as both the technology and threat landscape change.



Comments
Post a Comment